Thursday, February 19, 2015

PeopleTools 8.54: Global Temporary Tables

This is part of a series of articles about new features and differences in PeopleTools 8.54 that will be of interest to the Oracle DBA.

Database Feature Overview

Global Temporary tables were introduced in Oracle 8i.  They can be used where an application temporarily needs a working storage tables.  They are named
  • Global because the content is private
  • Temporary because the definition is permanent
Or if you prefer
  • Global because the definition is available to everyone
  • Temporary because 
    • physical instantiation of the table is temporary, in the temporary segment (so it isn't redo logged and so isn't recoverable),
    • but it does generate undo in the undo segment, and there is redo on the undo.
    • Each session gets its own private copy of the table in the temp segment.  So you cannot see what is in another session's temporary table, which can make application debugging difficult.
    • The physical instantiation of the table is removed either 
      • when the session disconnects - on commit preserve
      • or when the transaction is terminated with a commit or rollback - on commit delete
This is a very useful database feature (I have been using it in PeopleSoft application ever since it was introduced). 
  • Can be used for temporary records in Application Engines where restart is disabled.
  • Can be implemented without any application code change.
  • Only Application Designer temporary records can be built as global temporary tables.  You cannot make a SQL Table record global temporary.
  • The reduction in redo generation during intensive batch processes, such as payroll processing, can bring significant performance benefits.  There is no point logging redo information for temporary working storage tables that you do not ever need to restore.
  • Shared temporary tables, such as in the GP calculation process GPPDPRUN that is written in COBOL.  If using payroll streaming (multiple concurrent processes to process in parallel), then concurrent delete/update can cause read consistency problems when using a normal table, but with global temporary tables, each session has its own physical table so there is never any need to read consistency recover to read a global temporary tables.
  • Global temporary tables are also an effective way to resolve table high water mark issues that can occur on non-shared temporary tables in on-line application engine.  The PeopleTools %TruncateTable macro still resolves to delete.  You never get high water mark problems with global temporary tables because they are physically created afresh for each new session.  
  • There is often a reduction in database size because the tables are not retained after the session terminates.  Although there will be an increased demand for temporary tablespace while the global temporary tables are in use.
  • I have occasionally seen performance problems when PeopleSoft systems very frequently truncate tables and experience contention on the RO enqueue.  This problem does not occur with global temporary tables.
Global temporary table are not a licensed database feature and are also available in standard edition.

Global Temporary Tables in PeopleTools

This is the create table DDL created by Application Designer
DROP TABLE PS_ST_RM2_TAO
/
CREATE GLOBAL TEMPORARY TABLE PS_ST_RM2_TAO (PROCESS_INSTANCE
 DECIMAL(10) NOT NULL,
   EMPLID VARCHAR2(11) NOT NULL,
   GRANT_NBR VARCHAR2(10) NOT NULL,
   VEST_DT DATE,
   SHARES_REMAINDER DECIMAL(21, 9) NOT NULL,
   DEC_PLACES SMALLINT NOT NULL) ON COMMIT PRESERVE ROWS TABLESPACE PSGTT01
/
CREATE UNIQUE iNDEX PS_ST_RM2_TAO ON PS_ST_RM2_TAO (PROCESS_INSTANCE,
   EMPLID,
   GRANT_NBR,
   VEST_DT)
/
The first thing to point out is the specification of a tablespace.  This is a new feature in Oracle 11g.  It is not mandatory in Oracle, but it is coded into the PeopleSoft DDL model so you must specify a temporary tablespace on the record otherwise it will fail to build.  A new temporary tablespace PSGTT01 is delivered by Oracle when you upgrade to 8.54, or you could just use the existing temporary tables.

This new feature has been implemented using 2 new DDL models (statement types 6 and 7).
SELECT * FROM psddlmodel WHERE statement_type IN(6,7);

STATEMENT_TYPE PLATFORMID SIZING_SET  PARMCOUNT
-------------- ---------- ---------- ----------
MODEL_STATEMENT
------------------------------------------------------------------------
             6          2          0          0
CREATE GLOBAL TEMPORARY TABLE [TBNAME] ([TBCOLLIST]) ON COMMIT PRESERVE
ROWS TABLESPACE [TBSPCNAME];

             7          2          0          0
CREATE [UNIQUE] INDEX [IDXNAME] ON [TBNAME] ([IDXCOLLIST]);
  • All tables are created ON COMMIT PRESERVE, but online instances could be ON COMMIT DELETE (theory subject to testing) and for ALL application engine programs even if restart is enabled because commits are suppressed in online application engines.  Instead, the ommit is done by the component processor.
If you try adding a global temporary table table to an application engine that is not restart disabled you quite rightly get the following error message. The table will be added, but the program will not execute correctly.

"Global Temporary Tables allocated to this restart enabled AE program will not retain any data when program exits."

Problems:

  • There has always been a 13-character limit on temporary records, because there used to be a maximum of 99 non-shared instances, and 2 characters were reserved.  If you try to set the number of instances to greater than 99 in an application Engine (I tried GP_GL_PREP)  you now get the warning message
"Do not support more than 99 instances when selecting the Temp Table which are not attributed as GTT"
  • There is now a maximum length of 11 characters for the name of a record built a global temporary table because from PeopleTools 8.54 there can be up to 9999 non-shared instances of the record.  The restriction applies irrespective of how many instances you are actually using. 
    • I have yet to encounter a system where I need more than 99 instances of a temporary table.  I can just about imagine needing 100 non-shared instances, but not 1000.  
    • This means that I cannot retrofit global temporary tables into an existing Application Engine processes without changing record names.  There are existing delivered application engine programs with 12 and 13-character temporary record names that cannot now be switched to use global temporary tables managed by Application Designer.  I don't need to support more instances just because the table is global temporary.
      • For example, GP_GL_SEGTMP in GP_GL_PREP is a candidate to be made global temporary because that is a streamed Global Payroll process.  When I tried, I got a record name too long error!
"Record Name is too long. (47,67)"
    • Really, if the table is global temporary you don't need lots of instances.  Everyone could use the shared instance because Oracle gives each session a private physical copy of the table anyway. 
      • You could do this by removing the record name from the list of temporary records in the application engine, and then the %Table() macro will generate the table name without an instance number.
      • There would be a question of how to handle optimizer statistics.  Optimizer statistics collected on a global temporary table in one session could end up being used in another because there is only one place to store them in the data dictionary.
      • The answer is not to collect statistics at all and to use Optimizer Dynamic Sampling.  There is a further enhancement in Oracle 12c where the dynamically sampled stats from different sessions are kept separate.
  • When Application Designer builds an alter script, it can't tell whether it is a global temporary or normal table, so doesn't rebuild the table if you change it from one to the other.
  • The only real runtime downside of global temporary tables is that if you want to debug a process the data is not left behind after the process terminates.  Even while the process is running, you cannot query the contents of a global temporary table in use by another from your session,

My Recommendation

Support for global temporary tables is welcome and long overdue.  It can bring significant run time performance and system benefits due to the reduction in redo and read consistency.  It can be implemented without any code change. 

We just need to sort out the 11-character record name length restriction.

Wednesday, February 18, 2015

PeopleTools 8.54: Materialized Views

This is part of a series of articles about new features and differences in PeopleTools 8.54 that will be of interest to the Oracle DBA.

Materialized Views in the Database

Snapshots were introduced in Oracle 7.  They were a way of building and maintaining a physical table to hold the results of a SQL query.  We are well used to a view being the results of a query, but here the results are materialised into a physical table.  Hence the feature was renamed materialized views in Oracle 8i.

Today materialized views are one among many replication technologies.  They are available in standard edition Oracle, and there is no licensing implication in their use.

Materialized views can generally be put into two categories
  • A simple, single-table materialized view. 
    • Often used to replicate data across a database link from another database.  Or to produce a subset of the data.
    • Can be refreshed incrementally using a PL/SQL package supplied by Oracle
      •  A materialized view log is created on the source table to record all the changes made to the source table.  It holds the primary key of the changed row, or the rowid (physical address of the row).  It can optionally hold additional columns.  It is populated by a database trigger on the source table (since Oracle 8i that trigger is hidden).
  • Multi-table materialized view
    • Usually done within a single database rather than across a database link.
    • Can only be refreshed by being completely rebuilt. 
    • If the same query as is used in a materialized view is submitted, Oracle can rewrite the query to use the materialized view instead.  Query rewrite only occurs subject to configuration and certain pre-requisites being met.
Materialized Views can be populated immediately when they are built, or later on demand.  They can be refreshed on demand, on a regular schedule by a database job, or immediately when an update to a source table is committed.  Materialized views can be put into Refresh Groups.  All the materialized views in a refresh group are refreshed in the same database transaction so the data in the materialized views is consistent.

Materialized views can be updatable and used for bidirectional replication.  I am not going to talk that here.

When you introduce materialized views into an application you need to consider what you are trying to achieve, and make design decisions accordingly.

Materialized Views in PeopleTools 8.54

Using this new feature in PeopleSoft is deceptively easy, but quite a lot is going on behind the scenes.
PeopleSoft Documentation (the term PeopleBooks seems to have been replaced by PeopleSoft Online Help): Data Management, Using Materialized Views provides an overview.

There are two new PeopleTools tables:
  • PSPTMATVWDEFN - addition definition fields for the materialized view, build, refresh, staleness, stats.  Doesn't contain the query, that is in PSSQLTEXTDEFN as it is for all other views.
  • PSPTMATVWDEP - lists tables upon which materialized view depends.  PeopleSoft seems to work this out for itself by parsing the SQL query.
I am going to demonstrate some aspects of the feature by running through some examples.

Example 1: Replicate part of PS_JOB across a database link

In this example I am going to use a materialized view to replicate a table from another Oracle database across a database link.
If I select SQL View the Materialized View check box appears, if I check the checkbox the Materialized View Options appear.

This is build script generated by Application Designer
DROP VIEW PS_DMK
/
CREATE VIEW PS_DMK (EMPLID, EMPL_RCD, EFFDT, EFFSEQ, SETID_DEPT,
 DEPTID) AS SELECT EMPLID , EMPL_RCD , EFFDT , EFFSEQ , SETID_DEPT ,
 DEPTID FROM PS_JOB@HROTHER
/
UPDATE PSPTMATVWDEFN SET PTMAT_MATSTAT = 0, PTMAT_REFRESHSTAT = 0,
 PTMAT_LASTREFRESH = TO_TIMESTAMP('1900-01-01-00.00.00.000000'
,'YYYY-MM-DD-HH24.MI.SS.FF'), PTMAT_STALENESS = 'STALE' WHERE RECNAME
 = 'DMK'
/
DELETE FROM MV_CAPABILITIES_TABLE WHERE MVNAME = 'PS_DMK'
/
DROP VIEW PS_DMK
/
CREATE MATERIALIZED VIEW PS_DMK (EMPLID, EMPL_RCD, EFFDT, EFFSEQ,
 SETID_DEPT, DEPTID) TABLESPACE PSMATVW BUILD DEFERRED REFRESH FAST 
ON DEMAND DISABLE QUERY REWRITE AS SELECT EMPLID , EMPL_RCD , EFFDT ,
 EFFSEQ , SETID_DEPT , DEPTID FROM PS_JOB@HROTHER
/
UPDATE PSPTMATVWDEFN SET PTMAT_MATSTAT = 1, PTMAT_REFRESHSTAT = 0,
 PTMAT_LASTREFRESH = TO_TIMESTAMP('1900-01-01-00.00.00.000000'
,'YYYY-MM-DD-HH24.MI.SS.FF'), PTMAT_STALENESS = 'STALE' WHERE RECNAME
 = 'DMK'
/
However, if the materialized view already exists, the script will drop it, recreate and drop the view, and then recreate the materialized view.
DROP MATERIALIZED VIEW PS_DMK
/
UPDATE PSPTMATVWDEFN SET PTMAT_MATSTAT = 0, PTMAT_REFRESHSTAT = 0,
 PTMAT_LASTREFRESH = TO_TIMESTAMP('1900-01-01-00.00.00.000000'
,'YYYY-MM-DD-HH24.MI.SS.FF'), PTMAT_STALENESS = 'STALE' WHERE RECNAME
 = 'DMK'
/
CREATE VIEW PS_DMK (EMPLID, EMPL_RCD, EFFDT, EFFSEQ, SETID_DEPT,
 DEPTID) AS SELECT EMPLID , EMPL_RCD , EFFDT , EFFSEQ , SETID_DEPT ,
 DEPTID FROM PS_JOB@HROTHER
/
UPDATE PSPTMATVWDEFN SET PTMAT_MATSTAT = 0, PTMAT_REFRESHSTAT = 0,
 PTMAT_LASTREFRESH = TO_TIMESTAMP('1900-01-01-00.00.00.000000'
,'YYYY-MM-DD-HH24.MI.SS.FF'), PTMAT_STALENESS = 'STALE' WHERE RECNAME
 = 'DMK'
/
DELETE FROM MV_CAPABILITIES_TABLE WHERE MVNAME = 'PS_DMK'
/
DROP VIEW PS_DMK
/
CREATE MATERIALIZED VIEW PS_DMK (EMPLID, EMPL_RCD, EFFDT, EFFSEQ,
 SETID_DEPT, DEPTID) TABLESPACE PSMATVW BUILD IMMEDIATE REFRESH FAST
 ON DEMAND DISABLE QUERY REWRITE AS SELECT EMPLID , EMPL_RCD , EFFDT ,
 EFFSEQ , SETID_DEPT , DEPTID FROM PS_JOB@HROTHER
/
UPDATE PSPTMATVWDEFN SET PTMAT_MATSTAT = 1, PTMAT_REFRESHSTAT = 1,
 (PTMAT_LASTREFRESH, PTMAT_STALENESS) = (SELECT LAST_REFRESH_DATE, 
 STALENESS FROM USER_MVIEWS WHERE MVIEW_NAME = 'PS_DMK') WHERE RECNAME
  = 'DMK'
/
  • The Application Designer build script creates the materialized view using a primary key based replication.  If there is no WITH PRIMARY KEY clause specified, because it is the default.  There appears to be no way to get Application Designer to generate a WITH ROWID clause, so it is not possible to replicate a single table without a unique key.  You might question whether that is useful, but it is possible in Oracle.
  • If there is no primary key on the source table, you will to add one.  If this is on another system, or a pre-8.58 PeopleSoft system you will need to do this manually.  Otherwise you will get this error message:
ERROR at line 4:
ORA-12014: table 'PS_JOB' does not contain a primary key constraint 
  • If you specify any key columns on the materialized view it does not result in the usual indexes that you get on tables.  Also, it is not possible to add additional user specified indexes to the materialized view - the option is greyed out.  This is rather disappointing, because you might want to do exactly that so you can query the materialized view it in different ways to the underlying table.
    • You will get a unique index on a materialized view that is replicated by primary key, because the primary key will be inherited from the underlying table.
  • Nor is it possible to specify partitioning in Application Designer on a materialized view.
  • You can specify storage options on the materialized view via Record DDL, but the storage options do not appear in the CREATE MATERIALIZED VIEW statement in the build script.  This is rather disappointing because you don't need to provide free space for updates in a materialized view which is completely refreshed each time, but you might if you do incremental update.

Example 2: Replicate part of PS_JOB locally

In this example, I am again only replicating 6 named columns into my materialized view.
DROP VIEW PS_DMK
/
CREATE VIEW PS_DMK (EMPLID, EMPL_RCD, EFFDT, EFFSEQ, SETID_DEPT,
 DEPTID) AS SELECT EMPLID , EMPL_RCD , EFFDT , EFFSEQ , SETID_DEPT ,
 DEPTID FROM PS_JOB
/
UPDATE PSPTMATVWDEFN SET PTMAT_MATSTAT = 0, PTMAT_REFRESHSTAT = 0,
 PTMAT_LASTREFRESH = TO_TIMESTAMP('1900-01-01-00.00.00.000000'
,'YYYY-MM-DD-HH24.MI.SS.FF'), PTMAT_STALENESS = 'STALE' WHERE RECNAME
 = 'DMK'
/
ALTER TABLE PS_JOB DROP CONSTRAINT PS_JOB_PK
/
DROP MATERIALIZED VIEW LOG ON PS_JOB
/
DELETE FROM PSPTMATVWDEP WHERE RECNAME = 'DMK' AND PTMAT_BASETBL =
 'PS_JOB'
/
ALTER TABLE PS_JOB ADD CONSTRAINT PS_JOB_PK PRIMARY KEY (EFFDT, EFFSEQ
, EMPLID, EMPL_RCD)
/
CREATE MATERIALIZED VIEW LOG ON PS_JOB TABLESPACE PSMATVW WITH PRIMARY
 KEY, ROWID, SEQUENCE(DEPTID, SETID_DEPT) INCLUDING NEW VALUES PURGE
 IMMEDIATE
/
INSERT INTO PSPTMATVWDEP(RECNAME, PTMAT_BASETBL) VALUES('DMK',
 'PS_JOB')
/
DELETE FROM MV_CAPABILITIES_TABLE WHERE MVNAME = 'PS_DMK'
/
DROP VIEW PS_DMK
/
UPDATE PSPTMATVWDEFN SET PTMAT_MATSTAT = 0, PTMAT_REFRESHSTAT = 0,
 PTMAT_LASTREFRESH = TO_TIMESTAMP('1900-01-01-00.00.00.000000'
,'YYYY-MM-DD-HH24.MI.SS.FF'), PTMAT_STALENESS = 'STALE' WHERE RECNAME
 = 'DMK'
/
I don't know why it rebuilds the non-materialized view as a normal view and drops the primary key constraint each time every time but it does.  You might not want to do this every time for a large materialized view that takes time to build.
If the materialized view log has been built, next time you generate the view build script it creates and drop the view and then builds the materialized view.
CREATE VIEW PS_DMK (EMPLID, EMPL_RCD, EFFDT, EFFSEQ, SETID_DEPT,
 DEPTID) AS SELECT EMPLID , EMPL_RCD , EFFDT , EFFSEQ , SETID_DEPT ,
 DEPTID FROM PS_JOB
/
DELETE FROM PSPTMATVWDEP WHERE RECNAME = 'DMK' AND PTMAT_BASETBL =
 'PS_JOB'
/
UPDATE PSPTMATVWDEFN SET PTMAT_MATSTAT = 0, PTMAT_REFRESHSTAT = 0,
 PTMAT_LASTREFRESH = TO_TIMESTAMP('1900-01-01-00.00.00.000000'
,'YYYY-MM-DD-HH24.MI.SS.FF'), PTMAT_STALENESS = 'STALE' WHERE RECNAME
 = 'DMK'
/
ALTER TABLE PS_JOB DROP CONSTRAINT PS_JOB_PK
/
DROP MATERIALIZED VIEW LOG ON PS_JOB
/
DELETE FROM PSPTMATVWDEP WHERE RECNAME = 'DMK' AND PTMAT_BASETBL =
 'PS_JOB'
/
ALTER TABLE PS_JOB ADD CONSTRAINT PS_JOB_PK PRIMARY KEY (EFFDT, EFFSEQ
, EMPLID, EMPL_RCD)
/
CREATE MATERIALIZED VIEW LOG ON PS_JOB TABLESPACE PSMATVW WITH PRIMARY
 KEY, ROWID, SEQUENCE(DEPTID, SETID_DEPT) INCLUDING NEW VALUES PURGE
 IMMEDIATE
/
INSERT INTO PSPTMATVWDEP(RECNAME, PTMAT_BASETBL) VALUES('DMK',
 'PS_JOB')
/
DELETE FROM MV_CAPABILITIES_TABLE WHERE MVNAME = 'PS_DMK'
/
DROP VIEW PS_DMK
/
CREATE MATERIALIZED VIEW PS_DMK (EMPLID, EMPL_RCD, EFFDT, EFFSEQ,
 SETID_DEPT, DEPTID) TABLESPACE PSMATVW BUILD DEFERRED REFRESH FAST
 ON DEMAND DISABLE QUERY REWRITE AS SELECT EMPLID , EMPL_RCD , EFFDT ,
 EFFSEQ , SETID_DEPT , DEPTID FROM PS_JOB
/
UPDATE PSPTMATVWDEFN SET PTMAT_MATSTAT = 1, PTMAT_REFRESHSTAT = 1,
 (PTMAT_LASTREFRESH, PTMAT_STALENESS) = (SELECT LAST_REFRESH_DATE, 
 STALENESS FROM USER_MVIEWS WHERE MVIEW_NAME = 'PS_DMK') WHERE RECNAME
 = 'DMK'
/
  • It is rather odd to see a build script update a PeopleTools table. Application Designer also updates the PSPTMATVWDEFN table itself every time it generates the build script.  Note that the script doesn't issue an explicit commit, so if you execute the build script in SQL*Plus remember to commit to release the row level lock on PSPTMATVWDEFN.  
  • Application Designer flip-flops between these two build scripts that will repeatedly drop and create the materialized view and materialized view log.  Unless you are very careful you might not know whether you have the objects in the desired state.
  • The materialized view and materialized view log are always created in tablespace PSMATVW.  This is a new tablespace delivered in the standard tablespace script.  It is not possible to set the tablespace to something else as for a normal table because it is a view.  This is unfortunately because, I might not want all my materialized views in the same tablespace.
  • Even though the materialized view is replicated by primary key, the materialized view log also contains the rowid and the supplementary columns.  This is overkill.  The materialized view log as built be application designer contains every length-bounded column in the source table.  This can significantly increase the overhead of the materialized view log which is maintained as other process update the source table.
SQL> desc mlog$_ps_job
 Name                          Null?    Type
 ----------------------------- -------- -------------------
 EFFDT                                  DATE
 EFFSEQ                                 NUMBER
 EMPLID                                 VARCHAR2(11 CHAR)
 EMPL_RCD                               NUMBER
 DEPTID                                 VARCHAR2(10 CHAR)
 SETID_DEPT                             VARCHAR2(5 CHAR)
 M_ROW$$                                VARCHAR2(255 CHAR)
 SEQUENCE$$                             NUMBER
 SNAPTIME$$                             DATE
 DMLTYPE$$                              VARCHAR2(1 CHAR)
 OLD_NEW$$                              VARCHAR2(1 CHAR)
 CHANGE_VECTOR$$                        RAW(255)
 XID$$                                  NUMBER
    • If I just created the materialized view log as follows
CREATE MATERIALIZED VIEW LOG ON PS_JOB TABLESPACE PSMATVW 
WITH PRIMARY KEY
--, ROWID, SEQUENCE(DEPTID, SETID_DEPT) 
INCLUDING NEW VALUES PURGE IMMEDIATE
/
    • then the materialized view log contains fewer columns
Name                          Null?    Type
 ----------------------------- -------- --------------------
 EFFDT                                  DATE
 EFFSEQ                                 NUMBER
 EMPLID                                 VARCHAR2(11 CHAR)
 EMPL_RCD                               NUMBER
 SNAPTIME$$                             DATE
 DMLTYPE$$                              VARCHAR2(1 CHAR)
 OLD_NEW$$                              VARCHAR2(1 CHAR)
 CHANGE_VECTOR$$                        RAW(255)
 XID$$                                  NUMBER
  • The materialized view inherits the primary key from the source table because it is a single table materialized view replicated using the primary key.  Therefore there is also a unique index on this materialised view.
SELECT constraint_name, constraint_type, table_name, index_name
FROM   user_constraints
WHERE table_name = 'PS_DMK'
AND   constraint_type != 'C'
/

CONSTRAINT_NAME      C TABLE_NAME INDEX_NAME
-------------------- - ---------- ----------
PS_JOB_PK1           P PS_DMK     PS_JOB_PK1

SELECT index_name, index_type, uniqueness
FROM   user_indexes
WHERE  table_name = 'PS_DMK'
/

INDEX_NAME INDEX_TYPE UNIQUENES
---------- ---------- ---------
PS_JOB_PK1 NORMAL     UNIQUE

SELECT index_name, column_position, column_name, descend
FROM   user_ind_columns
WHERE  table_name = 'PS_DMK'
/

INDEX_NAME COLUMN_POSITION COLUMN_NAME          DESC
---------- --------------- -------------------- ----
PS_JOB_PK1               1 EFFDT                ASC
PS_JOB_PK1               2 EFFSEQ               ASC
PS_JOB_PK1               3 EMPLID               ASC
PS_JOB_PK1               4 EMPL_RCD             ASC


  • The build script clears out the MV_CAPABILITIES_TABLE when it drops the materialized view.  This table is used to hold the output from DBMS_MVIEW.EXPLAIN_MVIEW (see Oracle Database Data Warehousing Guide - ), which Application Designer executes when the materialized view record is saved.

  • Example 3:DMK_DPT_SEC_MVW is a materialised view that is cloned from security view DEPT_SEC_SRCH.

    This view references various tables (I have edited out column lists and predicates for readability)
    
    SELECT … 
      FROM PS_DEPT_TBL DEPT 
      , PSOPRDEFN OPR 
     WHERE EXISTS ( 
     SELECT 'X' 
      FROM PS_SJT_DEPT SEC 
      , PS_SJT_CLASS_ALL CLS 
      , PS_SJT_OPR_CLS SOC 
    …) 
        OR EXISTS ( 
     SELECT 'X' 
      FROM PS_SJT_DEPT SEC 
      , PS_SJT_CLASS_ALL CLS 
      , PS_SJT_OPR_CLS SOC 
     …) 
        OR EXISTS ( 
     SELECT 'X' 
      FROM PS_SJT_DEPT SEC 
      , PS_SJT_CLASS_ALL CLS 
      , PS_SJT_OPR_CLS SOC 
     …)
    
    But only 4 views appear in PSPTMATVWDEP.  PS_SJT_DEPT was not added.
    SELECT * FROM psptmatvwdep WHERE recname = 'DMK_DPT_SEC_MVW'
    /
    
    RECNAME         PTMAT_BASETBL
    --------------- ------------------
    DMK_DPT_SEC_MVW PSOPRDEFN
    DMK_DPT_SEC_MVW PS_DEPT_TBL
    DMK_DPT_SEC_MVW PS_SJT_CLASS_ALL
    DMK_DPT_SEC_MVW PS_SJT_OPR_CLS
    
    I think this is because it tried and failed to add primary key constraint and materialized view log to PS_SJT_DEPT because it has a 'duplicate key' defined in Application Designer.  The following errors are found in the build log even if the build script is not executed.
    ALTER TABLE PS_SJT_DEPT ADD CONSTRAINT PS_SJT_DEPT_PK PRIMARY KEY 
    (SCRTY_KEY1, SCRTY_KEY2, SCRTY_KEY3, SCRTY_TYPE_CD, SETID) 
    Error: DMK_DPT_SEC_MVW - SQL Error. Error Position: 39  Return: 2437 
    - ORA-02437: cannot validate (SYSADM.PS_SJT_DEPT_PK) - primary key violated 
     
    CREATE MATERIALIZED VIEW LOG ON PS_SJT_DEPT TABLESPACE PSMATVW 
    WITH PRIMARY KEY, ROWID, SEQUENCE (DEPTID, EFFDT_NOKEY) 
    INCLUDING NEW VALUES PURGE IMMEDIATE 
    Error: DMK_DPT_SEC_MVW - SQL Error. Error Position: 39  Return: 2437 
    - ORA-02437: cannot validate (SYSADM.PS_SJT_DEPT_PK) - primary key violated 
    
    Application Designer worked out that PS_SJT_DEPT was referenced in the materialized view query, but it didn't check that the table does not has a unique key defined in PeopleTools.

    We didn't get as far as creating the materialized view.  However, Application Designer passed the create Materialized View command to the EXPLAIN_MVIEW function in order to populate
    EXECUTE DBMS_MVIEW.EXPLAIN_MVIEW (q'[CREATE MATERIALIZED VIEW PS_DMK_DPT_SEC_MVW (SETID, OPRID, DEPTID, DESCR
    , DESCRSHORT, SETID_LOCATION, LOCATION, MANAGER_ID, COMPANY, USE_BUDGETS, USE_ENCUMBRANCES) 
    TABLESPACE PSMATVW BUILD DEFERRED REFRESH FAST ON DEMAND  AS 
    SELECT   DEPT.SETID, OPR.OPRID,  DEPT.DEPTID , DEPT.DESCR , DEPT.DESCRSHORT , DEPT.SETID_LOCATION 
    , DEPT.LOCATION , DEPT.MANAGER_ID , DEPT.COMPANY , DEPT.USE_BUDGETS , DEPT.USE_ENCUMBRANCES 
    FROM PS_DEPT_TBL DEPT , PSOPRDEFN OPR 
    WHERE EXISTS ( 
     SELECT 'X' FROM PS_SJT_DEPT SEC , PS_SJT_CLASS_ALL CLS , PS_SJT_OPR_CLS SOC 
     WHERE SEC.SETID = DEPT.SETID AND SEC.DEPTID = DEPT.DEPTID AND SEC.EFFDT_NOKEY = DEPT.EFFDT 
     AND CLS.SCRTY_SET_CD = 'PPLJOB' AND CLS.SCRTY_TYPE_CD = '001' AND CLS.TREE = 'Y' 
     AND CLS.SCRTY_KEY1 = SEC.SCRTY_KEY1 AND CLS.SCRTY_KEY2 = SEC.SCRTY_KEY2 
     AND CLS.SCRTY_KEY3 = SEC.SCRTY_KEY3 AND SOC.OPRID

    Example 4: DMK_JOB_CUR_MVW is a materialized view cloned from JOB_CURR_ALL_VW

    In this case I will try to create a materialized view on a complex query, but this time the underlying table has a unique key.  When I try to build the materialized view I get the following entries in the error log.  These warnings were obtained from the entries in MV_CAPABILITIES_TABLE which was populated by an attempt to describe the query.
    SQL Build process began on 16/02/2015 at 21:05:30 for database HR92U011. 
    Error: Cannot create Materialized View on record DMK_JOB_CUR_MVW. 
    Warning: | PS_DMK_JOB_CUR_MVW | REFRESH_COMPLETE| Y |  | | 
    Warning: | PS_DMK_JOB_CUR_MVW | REFRESH_FAST| N |  | | 
    Warning: | PS_DMK_JOB_CUR_MVW | REWRITE| N |  | | 
    Warning: | PS_DMK_JOB_CUR_MVW | REFRESH_FAST_AFTER_INSERT| N | aggregate function in mv | | 
    Warning: | PS_DMK_JOB_CUR_MVW | REFRESH_FAST_AFTER_INSERT| N | multiple instances of the same table or view | | 
    Warning: | PS_DMK_JOB_CUR_MVW | REFRESH_FAST_AFTER_ONETAB_DML| N | see the reason why REFRESH_FAST_AFTER_INSERT is disabled | | 
    Warning: | PS_DMK_JOB_CUR_MVW | REFRESH_FAST_AFTER_ANY_DML| N | see the reason why REFRESH_FAST_AFTER_ONETAB_DML is disabled | | 
    Warning: | PS_DMK_JOB_CUR_MVW | REWRITE_FULL_TEXT_MATCH| N | Oracle error: see RELATED_NUM and RELATED_TEXT for details |expression not supported for query rewrite | 
    Warning: | PS_DMK_JOB_CUR_MVW | REWRITE_FULL_TEXT_MATCH| N | Oracle error: see RELATED_NUM and RELATED_TEXT for details |expression not supported for query rewrite | 
    Warning: | PS_DMK_JOB_CUR_MVW | REWRITE_FULL_TEXT_MATCH| N | query rewrite is disabled on the materialized view | | 
    Warning: | PS_DMK_JOB_CUR_MVW | REWRITE_PARTIAL_TEXT_MATCH| N | materialized view cannot support any type of query rewrite | | 
    Warning: | PS_DMK_JOB_CUR_MVW | REWRITE_PARTIAL_TEXT_MATCH| N | query rewrite is disabled on the materialized view | | 
    Warning: | PS_DMK_JOB_CUR_MVW | REWRITE_GENERAL| N | subquery present in the WHERE clause | | 
    Warning: | PS_DMK_JOB_CUR_MVW | REWRITE_GENERAL| N | materialized view cannot support any type of query rewrite | | 
    Warning: | PS_DMK_JOB_CUR_MVW | REWRITE_GENERAL| N | query rewrite is disabled on the materialized view | | 
    
    SQL Build process ended on 16/02/2015 at 21:05:30. 
    1 records processed, 1 errors, 15 warnings. 
    SQL Build script for all processes written to file C:\Temp\PSBUILD.SQL. 
    SQL executed online. 
    SQL Build log file written to C:\Temp\PSBUILD.LOG.
    
    • So, Application Designer does try to prevent you from creating materialized views that Oracle won't manage, but the messages back are a little obscure.
    • If I change the refresh mode to Complete, Application Designer does not create materialized view logs. 
    CREATE MATERIALIZED VIEW PS_DMK_JOB_CUR_MVW (EMPLID, EMPL_RCD,
     ACTION_DT, BUSINESS_UNIT, EMPL_STATUS, HR_STATUS, DEPTID, JOBCODE,
     LOCATION, POSITION_NBR, ACTION, ACTION_REASON, COMP_FREQUENCY,
     COMPRATE, CURRENCY_CD, SAL_ADMIN_PLAN, GRADE, COMPANY, PAY_SYSTEM_FLG
    , PAYGROUP, REG_TEMP, FULL_PART_TIME, SETID_DEPT, SETID_JOBCODE,
     SETID_LOCATION, PER_ORG) TABLESPACE PSMATVW BUILD IMMEDIATE REFRESH
     COMPLETE ON DEMAND AS SELECT A.EMPLID ,A.EMPL_RCD ,A.EFFDT 
    ,A.BUSINESS_UNIT ,A.EMPL_STATUS ,A.HR_STATUS ,A.DEPTID ,A.JOBCODE 
    ,A.LOCATION ,A.POSITION_NBR ,A.ACTION ,A.ACTION_REASON 
    ,A.COMP_FREQUENCY ,A.COMPRATE ,A.CURRENCY_CD ,A.SAL_ADMIN_PLAN 
    ,A.GRADE ,A.COMPANY ,A.PAY_SYSTEM_FLG ,A.PAYGROUP ,A.REG_TEMP 
    ,A.FULL_PART_TIME ,A.SETID_DEPT ,A.SETID_JOBCODE ,A.SETID_LOCATION 
    ,A.PER_ORG FROM PS_JOB A WHERE A.EFFDT = ( SELECT MAX (C.EFFDT) FROM
     PS_JOB C WHERE C.EMPLID = A.EMPLID AND C.EMPL_RCD = A.EMPL_RCD AND
     ((C.EFFDT <= TO_DATE(TO_CHAR(SYSDATE,'YYYY-MM-DD'),'YYYY-MM-DD')) OR
     (A.EFFDT > TO_DATE(TO_CHAR(SYSDATE,'YYYY-MM-DD'),'YYYY-MM-DD') AND
     TO_DATE(TO_CHAR(SYSDATE,'YYYY-MM-DD'),'YYYY-MM-DD') < ( SELECT
     MIN(J2.EFFDT) FROM PS_JOB J2 WHERE J2.EMPLID = A.EMPLID AND
     J2.EMPL_RCD = A.EMPL_RCD) ) )) AND A.EFFSEQ = ( SELECT MAX(D.EFFSEQ)
     FROM PS_JOB D WHERE D.EMPLID = A.EMPLID AND D.EMPL_RCD = A.EMPL_RCD
     AND D.EFFDT = A.EFFDT)
    /
    UPDATE PSPTMATVWDEFN SET PTMAT_MATSTAT = 1, PTMAT_REFRESHSTAT = 1,
     (PTMAT_LASTREFRESH, PTMAT_STALENESS) = (SELECT LAST_REFRESH_DATE, 
     STALENESS FROM USER_MVIEWS WHERE MVIEW_NAME = 'PS_DMK_JOB_CUR_MVW')
     WHERE RECNAME = 'DMK_JOB_CUR_MVW'
    /
    
    • Also, It doesn't create a primary key constraint on either the underlying table or the materialized view.  So this materialized view doesn't have any indexes.

    Query ReWrite

    One common use of complex materialized views is to allow the optimizer to rewrite the query to use the materialized view when it sees the same query as was used to create the materialized view.  Optionally the optimizer will also check that the view is up to date.  I have added the enable query rewrite clause.
    DROP MATERIALIZED VIEW PS_DMK_PER_DEP_MVW
    /
    CREATE MATERIALIZED VIEW PS_DMK_PER_DEP_MVW (SETID_DEPT, DEPTID, EFFDT
    , DESCR) TABLESPACE PSMATVW 
    BUILD IMMEDIATE REFRESH COMPLETE ON DEMAND
    enable query rewrite
     AS SELECT A.SETID ,A.DEPTID ,A.EFFDT ,A.DESCR FROM PS_DEPT_TBL A
     WHERE A.EFFDT= ( SELECT MAX(B.EFFDT) FROM PS_DEPT_TBL B WHERE A.SETID
     =B.SETID AND A.DEPTID= B.DEPTID AND B.EFFDT<=TO_DATE(TO_CHAR(SYSDATE
    ,'YYYY-MM-DD'),'YYYY-MM-DD'))
    /
    
    However, expressions - in this case one generated to determine the current effective-dated department - are not supported for query write.
    =B.SETID AND A.DEPTID= B.DEPTID AND B.EFFDT<=TO_DATE(TO_CHAR(SYSDATE
                                                                  *
    ERROR at line 7:
    ORA-30353: expression not supported for query rewrite
    
    This could make it very difficult to use the feature in PeopleSoft. If you want to use the materialized view you are likely to have to reference it explicitly in the code.

    Refreshing materialized Views

    There is a new component to manage the refresh frequency of materialized views.
    PeopleTools-> Utilities-> Administration -> Oracle Materialized Views -> Materialized View Maintenance
    This component will schedule an Application Engine process called PTMATREFVW.
    What this Application Engine actually does is to specify the refresh frequency for the materialized view
    &AlterSQL = "alter materialized view " | &mview_name 
    | " REFRESH  NEXT SYSDATE + (" | &MatRecords.PTMAT_REFINT.Value | "/86400)";
    
    So the command issued is just
    alter materialized view PS_DMK REFRESH  NEXT SYSDATE + (4242/86400)";
    
    Effectively, for each materialized view, this creates a refresh group and a database job that refreshes it.
    SELECT rname, next_date, interval FROM user_refresh
    /
    
    RNAME      NEXT_DATE INTERVAL
    ---------- --------- -------------------------
    PS_DMK     24-JAN-15 SYSDATE + (4242/86400)
    
    SELECT name, type, rname, job, next_date, interval FROM user_refresh_children
    /
    
    NAME       TYPE       RNAME             JOB NEXT_DATE INTERVAL
    ---------- ---------- ---------- ---------- --------- -------------------------
    PS_DMK     SNAPSHOT   PS_DMK             21 24-JAN-15 SYSDATE + (4242/86400)
    
    SELECT job, next_date, next_Sec, interval, what FROM dba_jobs
    /
    
           JOB NEXT_DATE NEXT_SEC INTERVAL
    ---------- --------- -------- -------------------------
    WHAT
    --------------------------------------------------
            21 24-JAN-15 11:48:52 SYSDATE + (4242/86400)
    dbms_refresh.refresh('"SYSADM"."PS_DMK"');
    
    • But I might want to group related materialized views together into a single refresh group.
    • I might want to refresh the job at a particular time, which can be done with a more sophisticated function in the interval. 
    • I might prefer to refresh a materialized view at a particular point in a batch schedule.  So I might prefer to code that into an application engine, or have the application engine submit a job that only fires once and does resubmit (depending on whether I want to wait for the refresh).

    My Recommendations

    • Good Things
      • The removal of the descending indexes and the creation of the primary key is a good thing
      • It is useful to be able to define the materialized view query in PeopleTools along with the rest of the applicaiton.
      • The use of EXPLAIN_MVIEW to test the validity of the materialized view and to populate MV_CAPABILITIES_TABLE is clever, but the messages are obscure and should be better documented.
    • Bad Things
      • No checking that a source table in the local database doesn't have a unique key that will support a primary key.
      • I can't build indexes on materialized view.  Although, the primary key will be inherited automatically on single table materialized views.  So you will have to handle that manually outside PeopleTools.
      • There is no support for rowid based materialized views.
      • The materialized view logs created by Application Designer are totally overblown - there is far too much data being logged.  They should be either primark key or rowid (if primary key is not possible), but not both.  I cannot see the point of the additional columns.  I think they are a waste of resource.
      • The flip-flopping of the build script is confusing; you will never be completely sure what you have in the database. 
      • The script dropping the materialized view unnecessarily, which will drop any indexes that you have created manually!
    • I think some of the problems stem from trying to graft materialized views onto the existing view record type, instead of creating a new record type and building it into Application Designer properly and giving it the attributes of both a table and a view.
    • There is not enough control over when a materialized view is refreshed.  Just a time interval is not good enough.  In most systems, you need better control.
    • It is clearly going to be difficult getting database query rewrite to work with complex materialized views in PeopleSoft, especially if effective-date logic is required.  However, that is a reflection on the application code rather than the way support for materialized views has been implemented.
     When you design materialized views into your application you need to make careful choices about
    • Refresh method
      • Complete - pretty much mandatory for multi-table views, but there are some exceptions to this rule described in the Oracle database documentation.
      • Fast - only for single table - rarely used within a single database - more commonly used for moving data between databases.  In which case, you need database links and the materialized view log goes onto the source database and the materialized view is created on the target.
    • Refresh mode
      • On commit - this is potentially dangerous because it could happen too often and there won't be a saving.  Possible exception being when the underlying table is only ever updated by a batch process
      • On demand - manually issue refresh at a specific point in a batch
      • On schedule by a database job.
    • Build options
      • Immediate - the materialized view is populated when it is created
      • Deferred - the materialized view is not poplulated when it is created, and will have to be completely refreshed at some point in the future.
    Choice of refresh method and mode is often a function question.  How stale can the materialized view be allowed to be, especially if you can't get query rewrite to work.  Thoughtful design is required.  I have seen systems severely degraded by the query and redo overhead of excessive refresh. 
    PeopleTools support of materialized views certainly has some good things, but as it stands it is of limited use when it still leaves you with a lot of manual administration to do. 

    In most systems it is the DBAs who will have to manage the materialized views.  They are generally resistant to using PeopleSoft specific tools to do database administration.  That is going to be even more challenging when only a part of the job can be done in PeopleSoft.

    Monday, February 16, 2015

    PeopleTools 8.54: Descending Indexes are not supported

    This is the first in a series of articles about new features and differences in PeopleTools 8.54 that will be of interest to the Oracle DBA.

    "With PeopleTools 8.54, PeopleTools will no longer support descending indexes on the Oracle database platform" - PeopleTools 8.54 Release Notes

    They have gone again!  Forgive the trip down memory lane, but I think it is worth reviewing their history.
    • Prior to PeopleTools 8.14, if you specified a key or alternate search field in record as descending then where it appeared in automatically generated key and alternate search key indexes, that column would be descending.  PeopleTools would add the DESC keyword after the column in the CREATE INDEX DDL.  Similarly, columns can be specified as descending in user indexes (that is to say ones created by the developer with index ID A through Z).
    • In PeopleTools 8.14 to 8.47, descending indexes were not built by Application Designer because of a problem with the descending key indexes in some versions of Oracle 8i.  
      • PeopleSoft had previously recommended setting an initialisation parameter on 8i to prevent descending indexes from being created even if the DESC keyword was specified.parameters.
    _IGNORE_DESC_IN_INDEX=TRUE
    • From PeopleTools 8.48 the descending keyword came back because this was the first version of PeopleTools that was only certified from Oracle 9i, in which the descending index bug never occurred. (see blog posting 'Descending Indexes are Back!' October 2007).
    • In PeopleTools 8.54, there are again no descending indexes because the descending keyword has been omitted from the column list in the CREATE TABLE DDL. You can still specify descending keys in Application Designer because that controls the order in which rows are queried into scrolls in the PIA.  You can also still specify descending order on user indexes, but it has no effect upon either the application or the index DDL.
    I haven’t found any documentation that explains why this change has been made.  This time there is no suggestion of a database bug.  However, I think that there are a good database design reasons behind it.

    Normally creation of a primary key automatically creates a unique index to police the constraint.  It is possible to create a primary key constraint using a pre-existing index.  The index does not have to be unique, but it may as well.  However, there are some limitations.
    • You cannot create primary key on nullable columns - that is a fundamental part of the relational model.  This is rarely a problem in PeopleSoft where only dates that are not marked 'required' in the Application Designer are created nullable in the database.
      • You can create a unique index on nullable columns, which is probably why PeopleSoft has always used unique indexes.  
    • You cannot use a descending index in a primary key constraint because it is implemented as a function-based index.
    CREATE TABLE t (a NUMBER NOT NULL)
    /
    CREATE UNIQUE INDEX t1 ON t(A DESC)
    /
    ALTER TABLE t ADD PRIMARY KEY (a) USING INDEX t1
    /
    ORA-14196: Specified index cannot be used to enforce the constraint.
    
      • We can see that the descending key column is actually a function of a column and not a column, and so cannot be used in a primary key.
    SELECT index_name, index_type, uniqueness FROM user_indexes WHERE table_name = 'T'
    /
    
    INDEX_NAME INDEX_TYPE                  UNIQUENES
    ---------- --------------------------- ---------
    T1         FUNCTION-BASED NORMAL       UNIQUE 
    
    SELECT index_name, column_name, column_position, descend FROM user_ind_columns WHERE table_name = 'T'
    /
    
    INDEX_NAME COLUMN_NAME  COLUMN_POSITION DESC
    ---------- ------------ --------------- ----
    T1         SYS_NC00002$               1 DESC
    
    SELECT * FROM user_ind_expressions WHERE table_name = 'T'
    /
    
    INDEX_NAME TABLE_NAME COLUMN_EXPRESSION    COLUMN_POSITION
    ---------- ---------- -------------------- ---------------
    T1         T          "A"                                1
      • Non-PeopleSoft digression: you can create a primary key on a virtual column.  An index on the virtual column is not function-based.  So you can achieve the same effect if you move the function from the index into a virtual column, and you can have a primary key on the function.  However, PeopleTools Application Designer doesn't support virtual columns.
    I think that descending keys have removed from PeopleTools because:
    • It permits the creation of primary key constraints using the unique indexes.
    • It does not pose any performance threat.  In Oracle, index leaf blocks are chained in both directions so it is possible to use an ascending index for a descending scan and vice versa. 
    • Update 20.4.2016: There is an optimisation in Oracle 11.2.0.4 that improves the performance of the MAX() function in correlated sub-queries on ascending indexes only.  This will benefit all PeopleSoft applications, but especially HCM.
    What are the advantages of having a primary key rather than just a unique constraint?
    • The optimizer can only consider certain SQL transformations if there is a primary key.  That mainly affects star transformation.
    • It allows the optimizer to rewrite a query to use a materialized view. 
    • It allows a materialized view refresh to be based on the primary key rather than the rowid (the physical address of the row in a table).  This can save you from performing a full refresh of the materialized view if you rebuild the table (I will come back to materialized views in another posting).
    • If you are using logical standby, you need to be able to uniquely identify a row of data otherwise Oracle will perform supplemental logging.  Oracle will additionally log all bounded-size columns (in PeopleSoft, that means everything except LOBs).  Oracle can use non-null unique constraint, but it cannot use a unique function-based index.
      • Logical standby can be a useful way to minimise downtime during a migration.  For example, when migrating the database from a proprietary Unix to Linux where there is an Endian change.  Minimising supplemental logging would definitely be of interest in this case.
    The descending index change is not something that can be configured by the developer or administrator.  It is just something that is hard coded in Application Design and Data Mover that changes the DDL that they generate.

    There are some considerations on migration to PeopleTools 8.54:
    • It will be necessary to rebuild all indexes with descending keys to remove the descending keys.  
    • There are a lot of descending indexes in a typical PeopleSoft application (I counted the number of function-based indexes in a typical system: HR ~11000 , Financials: ~8500).  If you choose to do this during the migration it may take considerable time.
    • In Application Designer, if your build script settings are set to only recreate an index if modified, Application Designer will not detect that the index has a descending key and rebuild it.  So you will have to work out for yourself which indexes have descending key columns and handle the rebuild manually.
    • With migration to PeopleTools 8.54 in mind, you might choose to prevent Oracle from building descending indexes by setting _IGNORE_DESC_IN_INDEX=TRUE. Then you can handle the rebuild in stages in advance

    Conclusion

    I think the removal of descending indexes from PeopleSoft is a sensible change that enables a number of Oracle database features, while doing no harm.

    PeopleTools 8.54 for the Oracle DBA

    The UKOUG PeopleSoft Roadshow 2015 comes to London on 31st March 2015.  In a moment of enthusiasm, I offered to talk about new and interesting features of PeopleTools 8.54 from the perspective of an Oracle DBA.

    I have been doing some research, and have even read the release notes!  As a result, I have picked out some topics that I want to talk about.  I will discuss how the feature has been implemented, and what I think are the benefits and drawbacks of the feature:
    This post is not about a new feature in PeopleTools 8.54, but it is something that I discovered while investigating the new version.
    Links have been added to the above list as I have also blogged about each.  I hope it might produce some feedback and discussion.  After the Roadshow I will also add a link to the presentation.

    PeopleTools 8.54 is still quite new, and we are all still learning.  So please leave comments, disagree with what I have written, correct things that I have got wrong, ask questions.

    Monday, November 03, 2014

    Filtering PeopleTools SQL from Performance Monitor Traces


    I have been doing some on-line performance tuning on a PeopleSoft Financials system using PeopleSoft Performance Monitor (PPM).  End-users have collect verbose PPM traces. Usually, when I use PPM in a production system, all the components are fully cached by the normal activity of the user (except when the application server caches have recently been cleared).  However, when working in a user test environment it is common to find that the components are not fully cached. This presents two problems.
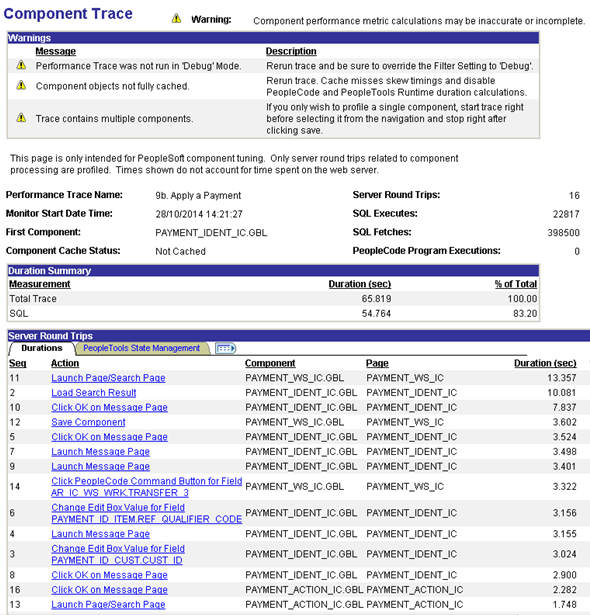
    • The application servers spend quite a lot of time executing queries on the PeopleTools tables to load the components, pages and PeopleCode into their caches. We can see in the screenshot of the component trace that there is a warning message that component objects are not fully cached, and that these  cache misses skew timings.
    • In verbose mode, the PPM traces collect a lot of additional transactions capturing executions and fetches against PeopleTools tables. The PPM analytic components cannot always manage the resultant volume of transactions.
    Figure 1. Component trace as collected by PPM
    Figure 1. Component trace as collected by PPM
    If I go further down the same page and look in the SQL Summary, I can see SQL operations against PeopleTools tables (they are easily identifiable in that they generally do not have an underscore in the third character). Not only are 5 of the top 8 SQL operations related to PeopleTools tables, we can also see that they also account for over 13000 executions, which means there are at least 13000 rows of additional data to be read from PSPMTRANSHIST.
    Figure 2. SQL Summary of PPM trace with PeopleTools SQL
    Figure 2. SQL Summary of PPM trace with PeopleTools SQL
    When I open the longest running server round trip (this is also referred to as a Performance Monitoring Unit or PMU), I can only load 1001 rows before I get a message warning that the maximum row limit has been reached. The duration summary and the number of executions and fetches cannot be calculated and hence 0 is displayed.
    Figure 3: Details of longest PMU with PeopleTools SQL
    Figure 3: Details of longest PMU with PeopleTools SQL

    Another consequence of the PeopleTools data is that it can take a long time to open the PMU tree. There is no screenshot of the PMU tree here because in this case I had so much data that I couldn't open it before the transaction timed out!

    Solution 

    My solution to this problem is to delete the transactions that relate to PeopleTools SQL and correct the durations, and the number of executions and fetches held in summary transactions. The rationale is that these transactions would not normally occur in significant quantities in a real production system, and there is not much I can do about them when they do.
    The first step is to clone the trace. I could work on the trace directly, but I want to preserve the original data.
    PPM transactions are held in the table PSPMTRANSHIST. They have a unique identifier PM_INSTANCE_ID. A single server round trip, also called a Performance Monitoring Unit (PMU), will consist of many transactions. They can be shown as a tree and each transaction has another field PM_PARENT_INST_ID which holds the instance of the parent. This links the data together and we can use hierarchical queries in Oracle SQL to walk the tree. Another field PM_TOP_INST_ID identifies the root transaction in the tree.
    Cloning a PPM trace is simply a matter of inserting data into PSPMTRANSHIST. However, when I clone a PPM trace I have to make sure that the instance numbers are distinct but still link correctly. In my system I can take a very simple approach. All the instance numbers actually collected by PPM are greater than 1016. So, I will simply use the modulus function to consistently alter the instances to be different. This approach may break down in future, but it will do for now.
    On an Oracle database, PL/SQL is a simple and effective way to write simple procedural processes.  I have written two anonymous blocks of code.
    Note that the cloned trace will be purged from PPM like any other data by the delivered PPM archive process.

    REM xPT.sql
    BEGIN --duplicate PPM traces
      FOR i IN (
        SELECT h.*
        FROM   pspmtranshist h
        WHERE  pm_perf_trace != ' ' /*rows must have a trace name*/
    --  AND    pm_perf_trace = '9b. XXXXXXXXXX' /*I could specify a specific trace by name*/
        AND    pm_instance_id > 1E16 /*only look at instance > 1e16 so I do not clone cloned traces*/
      ) LOOP
        INSERT INTO pspmtranshist 
        (PM_INSTANCE_ID, PM_TRANS_DEFN_SET, PM_TRANS_DEFN_ID, PM_AGENTID, PM_TRANS_STATUS,
        OPRID, PM_PERF_TRACE, PM_CONTEXT_VALUE1, PM_CONTEXT_VALUE2, PM_CONTEXT_VALUE3,
        PM_CONTEXTID_1, PM_CONTEXTID_2, PM_CONTEXTID_3, PM_PROCESS_ID, PM_AGENT_STRT_DTTM,
        PM_MON_STRT_DTTM, PM_TRANS_DURATION, PM_PARENT_INST_ID, PM_TOP_INST_ID, PM_METRIC_VALUE1,
        PM_METRIC_VALUE2, PM_METRIC_VALUE3, PM_METRIC_VALUE4, PM_METRIC_VALUE5, PM_METRIC_VALUE6,
        PM_METRIC_VALUE7, PM_ADDTNL_DESCR)
        VALUES
        (MOD(i.PM_INSTANCE_ID,1E16) /*apply modulus to instance number*/
        ,i.PM_TRANS_DEFN_SET, i.PM_TRANS_DEFN_ID, i.PM_AGENTID, i.PM_TRANS_STATUS,
        i.OPRID, 
        SUBSTR('xPT'||i.PM_PERF_TRACE,1,30) /*adjust trace name*/,
        i.PM_CONTEXT_VALUE1, i.PM_CONTEXT_VALUE2, i.PM_CONTEXT_VALUE3,
        i.PM_CONTEXTID_1, i.PM_CONTEXTID_2, i.PM_CONTEXTID_3, i.PM_PROCESS_ID, i.PM_AGENT_STRT_DTTM,
        i.PM_MON_STRT_DTTM, i.PM_TRANS_DURATION, 
        MOD(i.PM_PARENT_INST_ID,1E16), MOD(i.PM_TOP_INST_ID,1E16), /*apply modulus to parent and top instance number*/
        i.PM_METRIC_VALUE1, i.PM_METRIC_VALUE2, i.PM_METRIC_VALUE3, i.PM_METRIC_VALUE4, i.PM_METRIC_VALUE5, 
        i.PM_METRIC_VALUE6, i.PM_METRIC_VALUE7, i.PM_ADDTNL_DESCR);
      END LOOP;
      COMMIT;
    END;
    / 
    
    Now I will work on the cloned trace. I want to remove certain transaction.
    • PeopleTools SQL. Metric value 7 reports the SQL operation and SQL table name. So if the first word is SELECT and the second word is a PeopleTools table name then it is a PeopleTools SQL operation. A list of PeopleTools tables can be obtained from the object security table PSOBJGROUP.
    • Implicit Commit transactions. This is easy - it is just transaction type 425. 
    Having deleted the PeopleTools transactions, I must also
    • Correct transaction duration for any parents of transaction. I work up the hierarchy of transactions and deduct the duration of the transaction that I am deleting from all of the parent.
    • Transaction types 400, 427 and 428 all record PeopleTools SQL time (metric 66). When I come to that transaction I also deduct the duration of the deleted transaction from the PeopleTools SQL time metric in an parent transaction.
    • Delete any children of the transactions that I delete. 
    • I must also count each PeopleTools SQL Execution transaction (type 408) and each PeopleTools SQL Fetch transaction (type 414) that I delete. These counts are also deducted from the summaries on the parent transaction 400. 
    The summaries in transaction 400 are used on the 'Round Trip Details' components, and if they are not adjusted you can get misleading results. Without the adjustments, I have encountered PMUs where more than 100% of the total duration is spent in SQL - which is obviously impossible.
    Although this technique of first cloning the whole trace and then deleting the PeopleTools operations can be quite slow, it is not something that you are going to do very often. 
    REM xPT.sql
    REM (c)Go-Faster Consultancy Ltd. 2014
    set serveroutput on echo on
    DECLARE 
      l_pm_instance_id_m4 INTEGER;
      l_fetch_count INTEGER;
      l_exec_count INTEGER;
    BEGIN /*now remove PeopleTools SQL transaction and any children and adjust trans durations*/
      FOR i IN (
        WITH x AS ( /*returns PeopleTools tables as defined in Object security*/
          SELECT o.entname recname
          FROM   psobjgroup o
          WHERE  o.objgroupid = 'PEOPLETOOLS'
          AND    o.enttype = 'R'
        )
        SELECT h.pm_instance_id, h.pm_parent_inst_id, h.pm_trans_duration, h.pm_trans_defn_id
        FROM   pspmtranshist h
               LEFT OUTER JOIN x
               ON h.pm_metric_value7 LIKE 'SELECT '||x.recname||'%'
               AND x.recname = upper(regexp_substr(pm_metric_value7,'[^ ,]+',8,1)) /*first word after select*/
        WHERE  pm_perf_trace like 'xPT%' /*restrict to cloned traces*/
    --  AND    pm_perf_trace = 'xPT9b. XXXXXXXXXX' /*work on a specific trace*/
        AND    pm_instance_id < 1E16 /*restrict to cloned traces*/
        AND   (   x.recname IS NOT NULL 
               OR h.pm_trans_defn_id IN(425 /*Implicit Commit*/))
        ORDER BY pm_instance_id DESC
      ) LOOP
        l_pm_instance_id_m4 := TO_NUMBER(NULL);
     
        IF i.pm_parent_inst_id>0 AND i.pm_trans_duration>0 THEN
          FOR j IN(
            SELECT  h.pm_instance_id, h.pm_parent_inst_id, h.pm_top_inst_id, h.pm_trans_defn_id
            ,       d.pm_metricid_3, d.pm_metricid_4
            FROM    pspmtranshist h
              INNER JOIN pspmtransdefn d
              ON         d.pm_trans_defn_set = h.pm_trans_defn_set
              AND        d.pm_trans_defn_id = h.pm_trans_Defn_id
            START WITH h.pm_instance_id = i.pm_parent_inst_id
            CONNECT BY prior h.pm_parent_inst_id = h.pm_instance_id 
          ) LOOP
            /*decrement parent transaction times*/
            IF j.pm_metricid_4 = 66 /*PeopleTools SQL Time (ms)*/ THEN --decrement metric 4 on transaction 400
              --dbms_output.put_line('ID:'||i.pm_instance_id||' Type:'||i.pm_trans_defn_id||' decrement metric_value4 by '||i.pm_trans_duration);
              UPDATE pspmtranshist 
              SET    pm_metric_value4 = pm_metric_value4 - i.pm_trans_duration
              WHERE  pm_instance_id = j.pm_instance_id
              AND    pm_trans_Defn_id = j.pm_trans_defn_id
              AND    pm_metric_value4 >= i.pm_trans_duration
              RETURNING pm_instance_id INTO l_pm_instance_id_m4;
            ELSIF j.pm_metricid_3 = 66 /*PeopleTools SQL Time (ms)*/ THEN --SQL time on serialisation
              --dbms_output.put_line('ID:'||i.pm_instance_id||' Type:'||i.pm_trans_defn_id||' decrement metric_value3 by '||i.pm_trans_duration);
              UPDATE pspmtranshist 
              SET    pm_metric_value3 = pm_metric_value3 - i.pm_trans_duration
              WHERE  pm_instance_id = j.pm_instance_id
              AND    pm_trans_Defn_id = j.pm_trans_defn_id
              AND    pm_metric_value3 >= i.pm_trans_duration;
            END IF;
    
            UPDATE pspmtranshist 
            SET    pm_trans_duration = pm_trans_duration - i.pm_trans_duration
            WHERE  pm_instance_id = j.pm_instance_id
            AND    pm_trans_duration >= i.pm_trans_duration;
          END LOOP;
        END IF;
    
        l_fetch_count := 0;
        l_exec_count := 0;
        FOR j IN( /*identify transaction to be deleted and any children*/
          SELECT  pm_instance_id, pm_parent_inst_id, pm_top_inst_id, pm_trans_defn_id, pm_metric_value3
          FROM    pspmtranshist
          START WITH pm_instance_id = i.pm_instance_id
          CONNECT BY PRIOR pm_instance_id = pm_parent_inst_id 
        ) LOOP
          IF j.pm_trans_defn_id = 408 THEN /*if PeopleTools SQL*/
            l_exec_count := l_exec_count + 1;
          ELSIF j.pm_trans_defn_id = 414 THEN /*if PeopleTools SQL Fetch*/
            l_fetch_count := l_fetch_count + j.pm_metric_value3;
          END IF;
          DELETE FROM pspmtranshist h /*delete tools transaction*/
          WHERE h.pm_instance_id = j.pm_instance_id;
       END LOOP;
    
       IF l_pm_instance_id_m4 > 0 THEN 
         --dbms_output.put_line('ID:'||l_pm_instance_id_m4||' Decrement '||l_exec_Count||' executions, '||l_fetch_count||' fetches');
         UPDATE pspmtranshist  
         SET    pm_metric_value5 = pm_metric_value5 - l_exec_count
         ,      pm_metric_value6 = pm_metric_value6 - l_fetch_count
         WHERE  pm_instance_id = l_pm_instance_id_m4;
        l_fetch_count := 0;
        l_exec_count := 0;
       END IF;
    
      END LOOP;
    END;
    /
    
    Now, I have a second PPM trace that I can open in the analytic component.
    Figure 4: Original and Cloned PPM traces
    Figure 4: Original and Cloned PPM traces


    When I open the cloned trace, both timings in the duration summary have reduced as have the number of executions and fetches.  The durations of the individual server round trips have also reduced.
    Figure 5: Component Trace without PeopleTools transactions
    Figure 5: Component Trace without PeopleTools transactions

    All of the PeopleTools SQL operations have disappeared from the SQL summary.
    Figure 6: SQL Summary of PPM trace after removing PeopleTools SQL transactions
    Figure 6: SQL Summary of PPM trace after removing PeopleTools SQL transactions

    The SQL summary now only has 125 rows of data.
    Figure 7: SQL Summary of PMU without PeopleTools SQL

    Now, the PPM tree component opens quickly and without error.
    Figure 8: PMU Tree after removing PeopleTools SQL
    Figure 8: PMU Tree after removing PeopleTools SQL

    There may still be more transactions in a PMU than I can show in a screenshot, but I can now find the statement that took the most time quite quickly.

    Figure 9: Long SQL transaction further down same PMU tree
    Figure 9: Long SQL transaction further down same PMU tree

    Conclusions 

    I think that it is reasonable and useful to remove PeopleTools SQL operations from a PPM trace.
    In normal production operation, components will mostly be cached, and this approach renders traces collected in non-production environments both usable in the PPM analytic components and more realistic for performance tuning. However, it is essential that when deleting some transactions from a PMU, that summary data held in other transactions in the same PMU are also corrected so that the metrics remain consistent.