Tuesday, January 02, 2024

Controlling the Number of Database Scheduler (DBMS_SCHEDULER) Jobs That Can Execute Concurrently

The maximum number of database scheduler jobs that can run concurrently on each Oracle instance is primarily controlled by the parameter JOB_QUEUE_PROCESSES. The default value is the lesser of 20*CPU_COUNT or SESSIONS/4. I think 20 jobs per CPU is usually far too high because gives the scheduler the potential to swamp the CPU. Therefore, I usually reduce this parameter, often setting it to the same value as CPU_COUNT, so if you have 10 vCPUs per instance, you can run 10 concurrent jobs on each instance.  
However, this is a database-wide parameter. 
  • What if you want to restrict different jobs to a different number of concurrently executing instances? 
  • Or, you may have a more complex rule where different jobs have different weights? 
You can create a named resource with DBMS_SCHEDULER.CREATE_RESOURCE and give it a certain number of units. Then you can specify the number of units of which resource a particular job consumes with DBMS_SCHEDULER.SET_RESOURCE_CONSTRAINT. This must be done before the job is enabled, and then the job can be enabled afterward. 

Test 1: Separate Resources For Each Job

In this test: 
  • Each TEST_An job runs for 30 seconds and consumes 2 units of resource A, which has 10 units, so five jobs can run. 
  • Each TEST_Bn job runs for 30 seconds and consumes 1 unit of resource B, which has 3 units, so three jobs continue. 
  • The constraints on the two types of jobs are independent.
BEGIN
    DBMS_SCHEDULER.create_resource (
      resource_name    => 'TEST_RESOURCE_A',
      units            => 10,
      status           => 'ENFORCE_CONSTRAINTS',
      constraint_level => 'JOB_LEVEL');
    DBMS_SCHEDULER.create_resource (
      resource_name    => 'TEST_RESOURCE_B',
      units            => 3,
      status           => 'ENFORCE_CONSTRAINTS',
      constraint_level => 'JOB_LEVEL');
END;
/
BEGIN
   FOR i IN 1..10 LOOP
     dbms_scheduler.create_job (
       job_name=> 'TEST_A'||i,
       job_type=> 'PLSQL_BLOCK',
       job_action=> 'BEGIN DBMS_LOCK.SLEEP(30); END;',
       start_date=> sysdate,
       enabled=> false);
     dbms_scheduler.create_job (
       job_name=> 'TEST_B'||i,
       job_type=> 'PLSQL_BLOCK',
       job_action=> 'BEGIN DBMS_LOCK.SLEEP(30); END;',
       start_date=> sysdate,
       enabled=> false);
     DBMS_SCHEDULER.set_resource_constraint (
      object_name   => 'TEST_A'||i,
      resource_name => 'TEST_RESOURCE_A',
      units         => 2);     
     DBMS_SCHEDULER.set_resource_constraint (
      object_name   => 'TEST_B'||i,
      resource_name => 'TEST_RESOURCE_B',
      units         => 1);     
    dbms_scheduler.enable('TEST_A'||i);
    dbms_scheduler.enable('TEST_B'||i);
   END LOOP;
 END;
 /
You can see when each job started and finished in ALL_SCHEDULER_JOB_RUN_DETAILS.
set pages 99
column job_name format a8
column status format a10
clear screen
select log_id, log_date, job_name, status, actual_start_date, run_duration
from all_scheduler_job_run_details where job_name like 'TEST%' 
and actual_start_date >= TRUNC(SYSDATE)+…/24
order by actual_start_date
  • The first five TEST_A jobs and the first 3 TEST_B jobs ran. As the groups all finished after exactly 30s, new groups were run.  I've added spacing to illustrate the groups of jobs that run together.

    LOG_ID LOG_DATE                             JOB_NAME STATUS     ACTUAL_START_DATE                           RUN_DURATION       
---------- ------------------------------------ -------- ---------- ------------------------------------------- -------------------
   7747242 21/12/2023 06:42:42.106062000 -05:00 TEST_A1  SUCCEEDED  21/12/2023 11:42:11.578114000 EUROPE/LONDON +00 00:00:31.000000
   7747244 21/12/2023 06:42:42.105168000 -05:00 TEST_A2  SUCCEEDED  21/12/2023 11:42:11.924307000 EUROPE/LONDON +00 00:00:30.000000
   7747246 21/12/2023 06:42:42.615880000 -05:00 TEST_A3  SUCCEEDED  21/12/2023 11:42:12.171116000 EUROPE/LONDON +00 00:00:30.000000
   7747248 21/12/2023 06:42:42.615938000 -05:00 TEST_A4  SUCCEEDED  21/12/2023 11:42:12.208987000 EUROPE/LONDON +00 00:00:30.000000
   7747250 21/12/2023 06:42:42.615895000 -05:00 TEST_A5  SUCCEEDED  21/12/2023 11:42:12.247785000 EUROPE/LONDON +00 00:00:30.000000

   7747210 21/12/2023 06:42:43.680210000 -05:00 TEST_B1  SUCCEEDED  21/12/2023 11:42:13.323724000 EUROPE/LONDON +00 00:00:30.000000
   7747212 21/12/2023 06:42:43.681465000 -05:00 TEST_B5  SUCCEEDED  21/12/2023 11:42:13.356243000 EUROPE/LONDON +00 00:00:30.000000
   7747214 21/12/2023 06:42:43.680210000 -05:00 TEST_B2  SUCCEEDED  21/12/2023 11:42:13.387883000 EUROPE/LONDON +00 00:00:30.000000

   7747276 21/12/2023 06:43:17.947304000 -05:00 TEST_A6  SUCCEEDED  21/12/2023 11:42:47.543438000 EUROPE/LONDON +00 00:00:30.000000
   7747278 21/12/2023 06:43:17.947331000 -05:00 TEST_B3  SUCCEEDED  21/12/2023 11:42:47.543510000 EUROPE/LONDON +00 00:00:30.000000
   7747280 21/12/2023 06:43:17.949158000 -05:00 TEST_B4  SUCCEEDED  21/12/2023 11:42:47.758469000 EUROPE/LONDON +00 00:00:30.000000
   7747282 21/12/2023 06:43:17.947824000 -05:00 TEST_A7  SUCCEEDED  21/12/2023 11:42:47.759084000 EUROPE/LONDON +00 00:00:30.000000
   7747284 21/12/2023 06:43:18.457503000 -05:00 TEST_A8  SUCCEEDED  21/12/2023 11:42:47.966750000 EUROPE/LONDON +00 00:00:30.000000
   7747286 21/12/2023 06:43:18.457438000 -05:00 TEST_B6  SUCCEEDED  21/12/2023 11:42:48.063658000 EUROPE/LONDON +00 00:00:30.000000
   7747320 21/12/2023 06:43:19.008041000 -05:00 TEST_A10 SUCCEEDED  21/12/2023 11:42:48.846141000 EUROPE/LONDON +00 00:00:30.000000
   7747322 21/12/2023 06:43:19.008081000 -05:00 TEST_A9  SUCCEEDED  21/12/2023 11:42:48.846239000 EUROPE/LONDON +00 00:00:30.000000

   7747332 21/12/2023 06:43:49.215439000 -05:00 TEST_B9  SUCCEEDED  21/12/2023 11:43:19.165493000 EUROPE/LONDON +00 00:00:30.000000
   7747334 21/12/2023 06:43:49.729057000 -05:00 TEST_B7  SUCCEEDED  21/12/2023 11:43:19.262625000 EUROPE/LONDON +00 00:00:30.000000
   7747336 21/12/2023 06:43:49.726501000 -05:00 TEST_B8  SUCCEEDED  21/12/2023 11:43:19.262675000 EUROPE/LONDON +00 00:00:30.000000

   7747290 21/12/2023 06:44:23.992734000 -05:00 TEST_B10 SUCCEEDED  21/12/2023 11:43:53.567006000 EUROPE/LONDON +00 00:00:30.000000

Test 2: One Resource Used by Two Jobs

In this second test, both jobs use RESOURCE_A which still has 10 units.
BEGIN
  FOR i IN 1..10 LOOP
    dbms_scheduler.create_job (
      job_name=> 'TEST_A'||i,
      job_type=> 'PLSQL_BLOCK',
      job_action=> 'BEGIN DBMS_LOCK.SLEEP(30); END;',
      start_date=> sysdate,
      enabled=> false);
    dbms_scheduler.create_job (
      job_name=> 'TEST_B'||i,
      job_type=> 'PLSQL_BLOCK',
      job_action=> 'BEGIN DBMS_LOCK.SLEEP(30); END;',
      start_date=> sysdate,
      enabled=> false);
    DBMS_SCHEDULER.set_resource_constraint (
      object_name   => 'TEST_A'||i,
      resource_name => 'TEST_RESOURCE_A',
      units         => 2);     
    DBMS_SCHEDULER.set_resource_constraint (
      object_name   => 'TEST_B'||i,
      resource_name => 'TEST_RESOURCE_A', 
      units         => 1);     
    dbms_scheduler.enable('TEST_A'||i);
    dbms_scheduler.enable('TEST_B'||i);
  END LOOP;
END;
/
Now, we can run 5 TEST_A jobs and 10 test B jobs, or a combination. 
  • So initially we had 2 TEST_A jobs (that consume 4 units) and 6 TEST_B jobs (that consume 6 units). This completely consumed RESOURCE_A which only has 10 units.  No new jobs that use this resource could start until others were completed.
  • Next, we got 4 TEST_A jobs (that consume 8 units) and 2 TEST_B jobs (that consume 2 units), so again this consumed the whole of RESOURCE_A and again no further jobs could run that require this resource until others were completed.
    LOG_ID LOG_DATE                             JOB_NAME STATUS     ACTUAL_START_DATE                           RUN_DURATION       
---------- ------------------------------------ -------- ---------- ------------------------------------------- -------------------
   7747540 21/12/2023 13:40:10.170737000 -05:00 TEST_B1  SUCCEEDED  21/12/2023 18:39:39.718608000 EUROPE/LONDON +00 00:00:30.000000
   7747542 21/12/2023 13:40:10.169080000 -05:00 TEST_B2  SUCCEEDED  21/12/2023 18:39:39.971882000 EUROPE/LONDON +00 00:00:30.000000
   7747544 21/12/2023 13:40:10.169451000 -05:00 TEST_B3  SUCCEEDED  21/12/2023 18:39:40.012029000 EUROPE/LONDON +00 00:00:30.000000
   7747546 21/12/2023 13:40:10.680827000 -05:00 TEST_B4  SUCCEEDED  21/12/2023 18:39:40.258398000 EUROPE/LONDON +00 00:00:30.000000
   7747548 21/12/2023 13:40:10.680943000 -05:00 TEST_B5  SUCCEEDED  21/12/2023 18:39:40.300213000 EUROPE/LONDON +00 00:00:30.000000
   7747590 21/12/2023 13:40:10.680683000 -05:00 TEST_B6  SUCCEEDED  21/12/2023 18:39:40.343663000 EUROPE/LONDON +00 00:00:30.000000
   7747574 21/12/2023 13:40:11.231396000 -05:00 TEST_A1  SUCCEEDED  21/12/2023 18:39:40.730872000 EUROPE/LONDON +00 00:00:30.000000
   7747576 21/12/2023 13:40:11.231575000 -05:00 TEST_A5  SUCCEEDED  21/12/2023 18:39:40.786089000 EUROPE/LONDON +00 00:00:30.000000

   7747594 21/12/2023 13:40:40.376871000 -05:00 TEST_A2  SUCCEEDED  21/12/2023 18:40:10.271696000 EUROPE/LONDON +00 00:00:30.000000
   7747598 21/12/2023 13:40:40.888493000 -05:00 TEST_A6  SUCCEEDED  21/12/2023 18:40:10.679917000 EUROPE/LONDON +00 00:00:30.000000
   7747600 21/12/2023 13:40:40.889568000 -05:00 TEST_A7  SUCCEEDED  21/12/2023 18:40:10.680655000 EUROPE/LONDON +00 00:00:30.000000
   7747614 21/12/2023 13:40:41.401080000 -05:00 TEST_B10 SUCCEEDED  21/12/2023 18:40:11.304750000 EUROPE/LONDON +00 00:00:30.000000
   7747656 21/12/2023 13:40:42.975067000 -05:00 TEST_A3  SUCCEEDED  21/12/2023 18:40:12.598174000 EUROPE/LONDON +00 00:00:30.000000

   7747672 21/12/2023 13:40:51.168059000 -05:00 TEST_B9  SUCCEEDED  21/12/2023 18:40:21.061653000 EUROPE/LONDON +00 00:00:30.000000

   7747678 21/12/2023 13:41:13.183397000 -05:00 TEST_A4  SUCCEEDED  21/12/2023 18:40:42.789196000 EUROPE/LONDON +00 00:00:30.000000
   7747680 21/12/2023 13:41:13.182999000 -05:00 TEST_A8  SUCCEEDED  21/12/2023 18:40:43.093332000 EUROPE/LONDON +00 00:00:30.000000
   7747682 21/12/2023 13:41:13.183455000 -05:00 TEST_A9  SUCCEEDED  21/12/2023 18:40:43.093346000 EUROPE/LONDON +00 00:00:30.000000
   7747616 21/12/2023 13:41:16.729148000 -05:00 TEST_B7  SUCCEEDED  21/12/2023 18:40:46.287305000 EUROPE/LONDON +00 00:00:30.000000
   7747618 21/12/2023 13:41:16.729207000 -05:00 TEST_B8  SUCCEEDED  21/12/2023 18:40:46.287313000 EUROPE/LONDON +00 00:00:30.000000

   7747684 21/12/2023 13:41:23.423360000 -05:00 TEST_A10 SUCCEEDED  21/12/2023 18:40:53.317328000 EUROPE/LONDON +00 00:00:30.000000
You can also do this if you have a chain of sub-jobs. You would have a program that would be called for each step in the chain, and the resource constraint is applied to the program instead of the job. I will demonstrate this in another blog post.

Tuesday, December 19, 2023

Using Attribute Clustering to Improve Compression, Response Time and CPU Consumption: 2. An Example

Attribute Clustering reorders data in a table so that similar data values are clustered together.  This can improve both basic and columnar compression, resulting in better response time and lower CPU consumption.

This is the second of a two-part blog post.

  1. Introduction
  2. Example and Test Results

An Example of Attribute Clustering

This test illustrates the potential benefits of attribute clustering (the scripts are available on GitHub). It simulates the fact table in a data warehouse, or in my use case the General Ledger table in a Financials system. The table will have 20 million rows. Each dimension column will randomly have one of 256 distinct values, padded to 8 characters.  In this case, the distribution of data values is skewed by the square root function.  The alternative commented section produces uniform data. 
create table t0(a varchar2(8 char), b varchar2(8 char), c varchar2(8 char), x number);
truncate table t0;
BEGIN
  FOR i IN 1..2 LOOP
    insert  /*+APPEND PARALLEL*/ into t0
    select  /*+PARALLEL*/
/*--------------------------------------------------------------------------------------------------------------
            rPAD(LPAD(LTRIM(TO_CHAR(FLOOR(dbms_random.value(0,255)),'XX')),2,'0'),8,'X') a
    ,       rPAD(LPAD(LTRIM(TO_CHAR(FLOOR(dbms_random.value(0,255)),'XX')),2,'0'),8,'X') b
    ,       rPAD(LPAD(LTRIM(TO_CHAR(FLOOR(dbms_random.value(0,255)),'XX')),2,'0'),8,'X') c
--------------------------------------------------------------------------------------------------------------*/
            rPAD(LPAD(LTRIM(TO_CHAR(FLOOR(SQRT(dbms_random.value(0,65535))),'XX')),2,'0'),8,'X') a
    ,       rPAD(LPAD(LTRIM(TO_CHAR(FLOOR(SQRT(dbms_random.value(0,65535))),'XX')),2,'0'),8,'X') b
    ,       rPAD(LPAD(LTRIM(TO_CHAR(FLOOR(SQRT(dbms_random.value(0,65535))),'XX')),2,'0'),8,'X') c
--------------------------------------------------------------------------------------------------------------*/
    ,       dbms_random.value(1,1e6)
    from dual connect by level <= 1e7;
    COMMIT;
  end loop;
end;
/
exec dbms_stats.gather_table_stats(user,'T0');
I will create an identical materialized view on that table
create table mv(a varchar2(8 char), b varchar2(8 char), c varchar2(8 char), x number);
create materialized view mv on prebuilt table enable query rewrite as select * from t0;
For each test, I can set different attributes and then fully refresh the materialized view in non-atomic mode.  The various attributes take effect as the materialized view is truncated and repopulated in direct-path mode.
truncate table MV drop storage;
--------------------------------------------------
rem set compression
--------------------------------------------------
--alter materialized view MV nocompress;
--alter materialized view MV compress;
alter materialized view MV compress for query low;
--------------------------------------------------
rem set in memory
--------------------------------------------------
alter table mv inmemory;
--------------------------------------------------
rem set clustering and number of clustering columns
--------------------------------------------------
alter table mv drop clustering;
--alter table mv add clustering by interleaved order (b);
alter table mv add clustering by interleaved order (b, c);
--alter table mv add clustering by interleaved order (b, c, a);
--------------------------------------------------
exec dbms_mview.refresh('MV',atomic_refresh=>FALSE);
exec dbms_inmemory.repopulate(user,'MV');
Then I can see how large the physical and In-Memory segments are.
select * from user_mviews where mview_name = 'MV';
select table_name, tablespace_name, num_rows, blocks, compression, compress_for, inmemory, inmemory_compression 
from user_tables where table_name IN('MV','T0');
select segment_name, segment_type, tablespace_name, bytes/1024/1024 table_MB, blocks, extents, inmemory, inmemory_compression
from user_Segments where segment_name IN('MV','T0');

with x as (
select segment_type, owner, segment_name, inmemory_compression, inmemory_priority
, count(distinct inst_id) instances
, count(distinct segment_type||':'||owner||'.'||segment_name||'.'||partition_name) segments
, sum(inmemory_size)/1024/1024 inmemory_mb, sum(bytes)/1024/1024 tablespace_Mb
from   gv$im_segments i
where segment_name = 'MV'
group by segment_type, owner, segment_name, inmemory_compression, inmemory_priority)
select x.*, inmemory_mb/tablespace_mb*100-100 pct from x
order by owner, segment_type, segment_name
/
I will use a simple test query to see how the performance changes
select b,c, count(a), sum(x) from t0 where b='2AXXXXXX' group by b,c fetch first 10 rows only;
I tested 
  • Uniformly distributed data -v- skewed data
  • Without table compression -v- basic compression -v- Hybrid Columnar Compression (HCC)
  • No attribute clustering -v- interleaved clustering on 1, 2, and 3 columns
Table      Tablespace                                                                                         
Name       Name         NUM_ROWS     BLOCKS COMPRESS COMPRESS_FOR                   INMEMORY INMEMORY_COMPRESS
---------- ---------- ---------- ---------- -------- ------------------------------ -------- -----------------
MV         PSDEFAULT    20000000      60280 ENABLED  QUERY LOW                      ENABLED  FOR QUERY LOW    
T0         PSDEFAULT    20000000     150183 DISABLED                                DISABLED                  

                      Tablespace      Table                                                 
Segment Na Segment Ty Name               MB     BLOCKS    EXTENTS INMEMORY INMEMORY_COMPRESS
---------- ---------- ---------- ---------- ---------- ---------- -------- -----------------
MV         TABLE      PSDEFAULT       472.0      60416        130 ENABLED  FOR QUERY LOW    
T0         TABLE      PSDEFAULT     1,220.0     156160        203 DISABLED                  

                                                                                 In Memory Tablespace           
Segment Ty OWNER    Segment Na INMEMORY_COMPRESS INMEMORY  INSTANCES   SEGMENTS         MB         MB        PCT
---------- -------- ---------- ----------------- -------- ---------- ---------- ---------- ---------- ----------
TABLE      SYSADM   MV         FOR QUERY LOW     NONE              2          1      829.2      936.6 -11.4662752
With query rewrite on the materialized view and the materialized view in the In-Memory store, we see Oracle rewrite the query from the underlying table to the materialized view and then to an in-memory query.
select b,c, sum(x) from t0 where b='2AXXXXXX' group by b,c;

Plan hash value: 389206685
-----------------------------------------------------------------------------------------------
| Id  | Operation                              | Name | Rows  | Bytes | Cost (%CPU)| Time     |
-----------------------------------------------------------------------------------------------
|   0 | SELECT STATEMENT                       |      |   182 |  7280 |   876  (31)| 00:00:01 |
|   1 |  HASH GROUP BY                         |      |   182 |  7280 |   876  (31)| 00:00:01 |
|*  2 |   MAT_VIEW REWRITE ACCESS INMEMORY FULL| MV   | 78125 |  3051K|   875  (31)| 00:00:01 |
-----------------------------------------------------------------------------------------------

Test Results

Conclusions

  • Without any table compression, attribute clustering does not affect the size of the table on the tablespace, but the size of the table in the In-Memory store is reduced, and query performance is improved.
  • With either basic or Hybrid Columnar compression, attribute clustering reduces the size of the table both in the tablespace and in the in-memory store.
  • All forms of compression and attribute clustering increase the duration of the materialized view refresh. Degradation of the refresh due to clustering was less severe with HCC than with either no compression or simple compression.
  • I found that query performance degraded when using interleaved clustering in combination with simple compression although this resulted in a smaller in-memory segment than HCC, but performance improved with HCC.
  • Uniform data compressed marginally better than skewed.  Otherwise, they produced very similar results.  
  • You do not have to take advantage of compression on the physical segment to take advantage of the compression in In-Memory, but you may get better performance if you do.
  • With this test data set, optimal performance was achieved when clustering on 2 dimension columns. When clustering on all three columns I obtained worse compression and query performance. This varies with the data. With real-world data, I have had examples with better compression and performance with the maximum of 4 clustering column groups. Generally, the best performance corresponds to the attribute clustering that gives the best columnar compression. This is not always the case for simple compression.

Using Attribute Clustering to Improve Compression, Response Time and CPU Consumption: 1. Introduction

Attribute Clustering reorders data in a table so that similar data values are clustered together.  This can improve both basic and columnar compression, resulting in better response time and lower CPU consumption.

This is the first of a two-part blog post.

  1. Introduction
  2. Example and Test Results

Use Case

I am working on a Financials system running on an engineered system.  It runs a daily batch of GL reports on summary ledgers that have unindexed materialized views.  The materialized views are also hybrid column compressed (HCC) to reduce their size and improve reporting performance.  

We also put the materialized views into the In-Memory store.  Initially, we used 'free' base-level In-Memory and worked within the 16Gb/instance limit.  Having moved to Exadata Cloud@Customer, we can use the fully licensed version of In-Memory.

Now I have introduced Attribute Clustering for the materialized views.

Attribute Clustering

Attribute Clustering
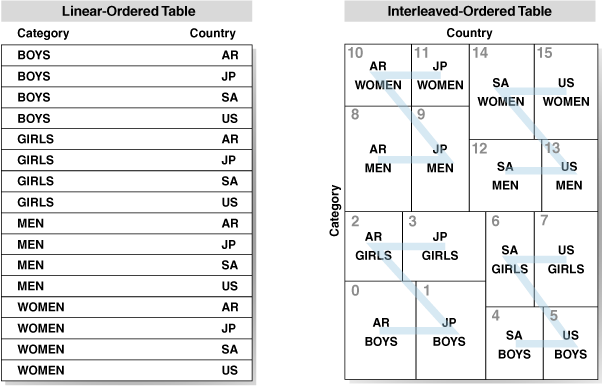
Attribute Clustering has been available on Enterprise Edition since Oracle 12.1.0.2.  Data is clustered in close physical proximity according to certain columns.  Linear Ordering stores the data according to the order of the specified clustering columns.  Interleaved Ordering uses a Z-order curve to cluster data in multiple dimensions (this graphic is from Oracle's documentation).

The GL reports have multiple combinations of different predicates. Therefore, as recommended by Oracle, we used interleaved ordering.  Linear ordering is not suitable in this case because there is no single suitable order for each table.  Linear ordering also caused the runtime of the materialized view refresh to extend much more than interleaved ordering as it has to sort the data.

We have not introduced Zone Maps.  That is to say that after testing, we removed them.  Zone maps can be thought of as a coarse index of the zones in the attribute clustering, and would normally be expected to improve the access of the data.  You can see them being used in the execution plans to access the table both in the tablespace and in the In-Memory store.  However, our application dynamically generates a lot of SQL and therefore performs a lot of SQL parse.  We found that the additional work to process the zone map significantly degraded performance.

Attribute Clustering is not enforced for every DML operation. It only affects direct-path insert operations, data movement, or table creation. It is easy to implement it for segments that are already HCC, which also relies on direct-path operations.  The materialized views were created to introduce HCC, hence they are refreshed in non-atomic mode which truncates and repopulates them in direct-path mode.  Thus attribute clustering specified on the materialized views will be implemented as they refresh.

Historical, and therefore static, partitions in the ledger tables are marked for HCC, and we schedule an online rebuild to compress them.  Now, that will also apply attribute clustering.  This process could be automated with Automatic Storage Compression.

Compression

Simply by storing similar data values together, we obtained better compression from HCC.  The tables underlying the materialized views were smaller.  

In-Memory also uses columnar compression.  Attribute clustering produced a reduction in the size of segments in the In-Memory store.  If we were still working within the constraints of Base-Level In-Memory, we would have been able to store more segments in In-Memory.

We are using attribute clustering not to directly improve data access, but to harness a secondary effect, that of improved compression.  We are seeing a reduction in the runtime of the reports.  Most of the database time is already spent on the CPU (as most of the fact tables are in In-Memory), so this translates to a reduction in CPU consumption.  We can consider running more reports concurrently to complete the batch earlier.  We can also consider reducing the number of CPUs and therefore reduce cloud subscription costs.

The second part of this blog will show an example test script and results.

Monday, November 27, 2023

Database Constraints Enforced but not Validated for New Data Now, but Not Existing Data

Recently, while discussing a problem, somebody said to me 'I would like to make this column NOT NULL to stop [this problem] from occurring, but first I would need to go back and fix all the historical data'. 
In Oracle, a constraint that is enabled will apply during DML, so as you insert or update the data, the constraint is applied to the rows that are being updated. Only when a constraint is validated, does the database check that all the data in the table conforms to the constraint.  
If you create a constraint that is enforced, but not validated, you may be able to prevent a problem from getting worse while you fix the data you already have.

A Demonstration 

I will create a table with a unique constraint and two other columns that are NOT NULL.  I put some data in the tables.  Column B is null for some of the rows, but not for others.
create table t (a number, b number, c number, constraint t_pk primary key(A));

insert into t (a,b)
select level, CASE WHEN MOD(level,2)=1 then 1 end --B is null on alternate rows
from dual connect by level<=10;

select * from t;

         A          B          C
---------- ---------- ----------
         1          1           
         2                      
         3          1           
         4                      
         5          1           
         6                      
         7          1           
         8                      
         9          1           
        10                      

10 rows selected.
I would like to make B a NOT NULL column (to stop the application from writing an invalid value to the database), but cannot because I already have some invalid values in the database.
SQL> alter table t modify b not null ;

ORA-02296: cannot enable (SCOTT.) - null values found
02296. 00000 - "cannot enable (%s.%s) - null values found"
*Cause:    an alter table enable constraint failed because the table
           contains values that do not satisfy the constraint.
*Action:   Obvious
However, I can create the constraint with the NOVALIDATE option.
SQL> alter table t modify b not null novalidate;

Table T altered.

SQL> select constraint_name, search_condition_vc from user_constraints where table_name = 'T';

CONSTRAINT_NAME SEARCH_CONDITION_VC                                         
--------------- ------------------------------------------------------------
T_PK                                                                        
SYS_C00221684   "B" IS NOT NULL
Note that at the moment column B is not described as NOT NULL because although the constraint is enforced, it has not been validated.
SQL> desc t
Name Null?    Type   
---- -------- ------ 
A    NOT NULL NUMBER 
B             NUMBER 
C             NUMBER
If I try to add more rows where some of the data in column B is null, the constraint prevents it.
SQL> insert into t (a,b)
  2  select level+10, CASE WHEN MOD(level,2)=1 then 1 end 
  3  from dual connect by level<=10;

ORA-01400: cannot insert NULL into ("SCOTT"."T"."B")
I can set B column to a NOT NULL value, but I cannot set it back to null.
SQL> update t set b = 2 where a=2;

1 row updated.

SQL> update t set b = NULL where a=2;

ORA-01407: cannot update ("SCOTT"."T"."B") to NULL
I can successfully update a different column on a row where B is null and therefore does not meet the constraint.  I do not get an error because I have not updated it.  
SQL> SQL> update t set c = a;

10 rows updated.
Eventually, I will want to validate the constraint so that I know that B has a not null value in all the rows. But I can't do it while there are still some null values
SQL> select * from t;

         A          B          C
---------- ---------- ----------
         1          1          1
         2          2          2
         3          1          3
         4                     4
         5          1          5
         6                     6
         7          1          7
         8                     8
         9          1          9
        10                    10

SQL> DECLARE
  2    l_sql CLOB;
  3  BEGIN
  4    FOR I IN (select * from user_constraints where table_name = 'T' AND constraint_type ='C' 
  5              and validated != 'VALIDATED' and search_condition_vc = '"B" IS NOT NULL') LOOP
  6      l_sql := 'alter table '||i.table_name||' modify constraint '||i.constraint_name||' VALIDATE';
  7      dbms_output.put_line(l_sql);
  8      EXECUTE IMMEDIATE l_sql;
  9    END LOOP;
 10  END;
 11  /
alter table T modify constraint SYS_C00221684 VALIDATE

ORA-02293: cannot validate (SCOTT.SYS_C00221684) - check constraint violated
ORA-06512: at line 7
02293. 00000 - "cannot validate (%s.%s) - check constraint violated"
*Cause:    an alter table operation tried to validate a check constraint to
           populated table that had nocomplying values.
*Action:   Obvious
First I have to fix the data, and then I can validate the constraint
SQL> UPDATE t set b=a where b is null;

4 rows updated.

SQL> REM now validate the constraint
SQL> BEGIN
  2    FOR I IN (select * from user_constraints where table_name = 'T' AND constraint_type ='C' 
  3              and validated != 'VALIDATED' and search_condition_vc = '"B" IS NOT NULL') LOOP
  4      EXECUTE IMMEDIATE 'alter table '||i.table_name||' modify constraint '||i.constraint_name||' VALIDATE';
  5    END LOOP;
  6  END;
  7  /

PL/SQL procedure successfully completed.
Only now that the new constraint has been validated is the column described as NOT NULL.
SQL> desc t
Name Null?    Type   
---- -------- ------ 
A    NOT NULL NUMBER 
B    NOT NULL NUMBER 
C             NUMBER

Friday, November 10, 2023

Prioritising Scheduled Processes by Operator ID/Run Control

Batch processing is like opera (and baseball) - "It ain't over till the fat lady sings".  Users care about when it starts and when it finishes.  If the last process finishes earlier, then that is an improvement in performance. 

This note describes a method of additionally prioritising processes queued to run on the process scheduler in PeopleSoft by their requesting operator ID and run control.  Where processing consists of more instances of the same process than can run concurrently, it can be used to make the process scheduler run longer-running processes before shorter-running processes that were scheduled earlier, thus completing batch processing earlier.

In PeopleSoft, without customisation, it is only possible to prioritise processes queued to run on the process scheduler by assigning a priority to the process definition or their process category.  Higher priority processes are selected to be run in preference to lower priorities.  Otherwise, processes are run in the order of the time at which they are requested to run.

Problem Statement

During an overnight batch, many nVision report books are scheduled to run on the Windows process schedulers by one of several specific batch operator IDs.  Many more reports are scheduled than can run concurrently, so some execute while others queue.  Inevitably, the reports have widely varying execution times.  The maximum concurrency of the nVision report book (RPTBOOK) process definition has been set, and the Oracle database resource manager has also been configured, to prevent too many of these processes from overloading the database.

CPU Utilisation of BatchThis chart shows the database activity when the batch runs.  We often see what has come to be called the 'long tail' while we wait for just a few long-running processes to complete.


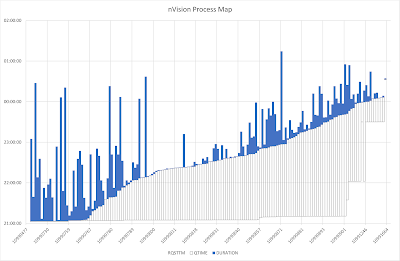
The next chart shows the processing time of each nVision report process.  The blue bars run from when the started to when it ended, ordered by start time.   The clear boxes below run from the time when it was requested to when it started, thus showing the period for which the processes were queued on a process scheduler, but were blocked because the maximum number of processes were already processing.
Process Map (without prioritisation)
All these processes run with the same priority because they are the same process definition.  Some long-running jobs execute earlier in the batch simply because they were scheduled earlier, but others that started later, run on beyond the end of the batch.  
It would be better if the longest-running processes were executed earlier, irrespective of the order in which they were requested.  Thus the shorter processes can run later as slots on the scheduler become free, and thus all processes should finished both closer together and earlier.
There is nothing delivered in the PeopleSoft process scheduler configuration that will let you assign different priorities to different executions of the same process.  In PeopleSoft, only three priorities are defined PRCSPRIORITY (1=Low, 5=Medium, 9=High) on the process definition and the server category.  These priorities are transferred to the process request queue (PSPRCSQUE.PRCSPRTY).  
If we could put our own priority into that column we could control the priority of the request.  

Solution

Introduce a database trigger that fires on insert into PSPRCSQUE and sets a priority specified on a new metadata table.  PRCSPRTY is not validated by PeopleSoft, and therefore any value can be specified.  
The files are available in a Github repository davidkurtz/psprcspty. The exact metadata will vary with the use case and requirements, but I provided some examples of how it might be generated.

Metadata Table: PS_XX_GFCPRCSPRTY

We need a table that will hold the priority for each combination of process type, process name, operation ID, and run control ID.  A corresponding record should be created using the Application Designer project in the GitHub repository.

create table sysadm.ps_xx_gfcprcsprty
(prcstype  VARCHAR2(30 CHAR) NOT NULL
,prcsname  VARCHAR2(12 CHAR) NOT NULL
,oprid     VARCHAR2(30 CHAR) NOT NULL
,runcntlid VARCHAR2(30 CHAR) NOT NULL
,prcsprty  NUMBER NOT NULL
--------------------optional columns
,avg_duration NUMBER NOT NULL
,med_duration NUMBER NOT NULL
,max_duration NUMBER NOT NULL
,cum_duration NUMBER NOT NULL
,tot_duration NUMBER NOT NULL
,num_samples  NUMBER NOT NULL
) tablespace ptapp;

create unique index sysadm.ps_xx_gfcprcsprty
on sysadm.ps_xx_gfcprcsprty(prcstype, prcsname, oprid, runcntlid) 
tablespace psindex compress 3;

Trigger Before Insert into PSPRCSQUE

As processes are scheduled in PeopleSoft, a row is inserted into the process scheduler queue table PSPRCSQUE.  A trigger will be created on this table that fires after the insert.  It will look for a matching row on the metadata table, PS_XX_GFCPRCSPRTY for the combination of process type, process name, operator ID, and run control ID.  If found, the trigger will assign the specified priority to the process request.  Otherwise, it will take no action.

CREATE OR REPLACE TRIGGER sysadm.psprcsque_set_prcsprty
BEFORE INSERT ON sysadm.psprcsque
FOR EACH ROW
WHEN (new.prcsname = 'RPTBOOK')
DECLARE
  l_prcsprty NUMBER;
BEGIN
  SELECT prcsprty
  INTO   l_prcsprty
  FROM   ps_xx_gfcprcsprty
  WHERE  prcstype = :new.prcstype
  AND    prcsname = :new.prcsname
  AND    oprid = :new.oprid
  AND    runcntlid = :new.runcntlid;
 
  :new.prcsprty := l_prcsprty;
EXCEPTION
  WHEN no_data_found THEN NULL;
  WHEN others THEN NULL;
END;
/
show errors

In this case, I am only assigning priorities to RPTBOOK processes, so I have added a when clause to the trigger so that it only fires for RPTBOOK process requests.  This can either be changed for other processes or removed entirely.

Priority Metadata

How the priorities should be defined will depend on the specific use case.  In some cases, you may choose to create a set of metadata that remains unchanged.

In this case, the objective is that the processes to take the longest to run should be executed first.  Therefore, I decided that the priority of each nVision report book process (by operator ID and run control ID) will be determined by the median elapsed execution time in the last two months.  The priorities are allocated such that the sum of the median execution times for each priority will be as even as possible.  

I have created a PL/SQL procedure GFCPRCSPRIORITY to truncate the metadata table and then repopulate it using a query on the process scheduler table (although, an Application Engine program could have been written to do this instead).  Some details of that query will vary with the exact use case. The procedure is executed daily, thus providing a feedback loop so if the run time varies over time, or new processes are added to the batch, it will be reflected in the priorities.

REM nvision_prioritisation_by_cumulative_runtime.sql

set serveroutput on
create or replace procedure sysadm.gfcprcspriority as
  PRAGMA AUTONOMOUS_TRANSACTION; --to prevent truncate in this procedure affecting calling session
  l_hist INTEGER := 61 ; --consider nVision processes going back this many days
begin
  EXECUTE IMMEDIATE 'truncate table ps_xx_gfcprcsprty';

--populate priorty table with known nVision processes 
insert into ps_xx_gfcprcsprty
with r as (
select r.prcstype, r.prcsname, r.prcsinstance, r.oprid, r.runcntlid, r.runstatus, r.servernamerun
, CAST(r.rqstdttm AS DATE) rqstdttm
, CAST(r.begindttm AS DATE) begindttm
, CAST(r.enddttm AS DATE) enddttm
from t, psprcsrqst r
  inner join ps.psdbowner p on r.dbname = p.dbname -- in test exclude any history copied from another database
where r.prcstype like 'nVision%' --limit to nVision processes
and r.prcsname like 'RPTBOOK' -- limit to report books
and r.enddttm>r.begindttm  --it must have run to completion
and r.oprid IN('NVISION','NVISION2','NVISION3','NVISION4')  --limit to overnight batch operator IDs
and r.begindttm >= TRUNC(SYSDATE)+.5-l_hist --consider process going back l_hist days from midday today
and r.runstatus = '9' --limit to successful processes
and r.begindttm BETWEEN ROUND(r.begindttm)-5/24 AND ROUND(r.begindttm)+5/24 --started between 7pm and 5am
), x as (
select r.*, CEIL((enddttm-begindttm)*1440) duration -–rounded up to the next minute
from r
), y as (
select prcstype, prcsname, oprid, runcntlid
, AVG(duration) avg_duration
, MEDIAN(CEIL(duration)) med_duration 
, MAX(duration) max_duration
, SUM(CEIL(duration)) sum_duration
, COUNT(*) num_samples
from x
group by prcstype, prcsname, oprid, runcntlid
), z as (
select y.* 
, sum(med_duration) over (order by med_duration rows between unbounded preceding and current row) cum_duration 
, sum(med_duration) over () tot_duration
from y
)
select prcstype, prcsname, oprid, runcntlid 
, avg_duration, med_duration, max_duration, cum_duration, tot_duration, num_samples
--, CEIL(LEAST(tot_duration,cum_duration)/tot_duration*3)*4-3 prcsprty  --3 priorities
, CEIL(LEAST(tot_duration,cum_duration)/tot_duration*9) prcsprty  --9 priorities
--, DENSE_RANK() OVER (order by med_duration) prcsprty --unlimited priorities
from z
order by prcsprty, cum_duration;

  dbms_output.put_line(sql%rowcount||' rows inserted');
  commit;

end gfcprcspriority;
/
show errors
In testing, I found that using just the 3 delivered levels of priority was not sufficiently granular to prioritise the jobs adequately, so I chose to use 9 levels (1 to 9).  The process priority on PRCSQUE is not validated, so I can use any value.  I also found I could just rank the processes from 1 to n by duration, and that would also work.

It is possible to create additional priority levels for process categories (see also More Process Priority Levels for the Process Scheduler), but that still only works for prioritising different processes over each other.

Metadata

This is the metadata produced on a test system by the above query.  It will vary depending on what has been run recently, and how it performed.  There are more, shorter processes in the lower priority groups, and fewer, longer processes in the higher priority groups.  

PRCSTYPE                       PRCSNAME     OPRID        RUNCNTLID                        PRCSPRTY
------------------------------ ------------ ------------ ------------------------------ ----------
…
nVision-ReportBook             RPTBOOK      NVISION2     NVS_RPTBK_XXX1                          1
nVision-ReportBook             RPTBOOK      NVISION2     NVS_RPTBK_XXX3                          1
nVision-ReportBook             RPTBOOK      NVISION2     NVS_RPTBK_LLLL8                         1
…
nVision-ReportBook             RPTBOOK      NVISION2     NVS_RPTBK_LLLL9                         2
nVision-ReportBook             RPTBOOK      NVISION      NVS_RPTBOOK_STAT8                       2
nVision-ReportBook             RPTBOOK      NVISION      NVS_RPTBOOK_STAT1                       2
…
nVision-ReportBook             RPTBOOK      NVISION2     NVS_RPTBK_TEMPXX                        6
nVision-ReportBook             RPTBOOK      NVISION      NVS_RPTBOOK_3                           6
nVision-ReportBook             RPTBOOK      NVISION      NVS_RPTBOOK_17                          6
nVision-ReportBook             RPTBOOK      NVISION      NVS_RPTBOOK_STAT4                       7
nVision-ReportBook             RPTBOOK      NVISION      NVS_RPTBOOK_28                          7
nVision-ReportBook             RPTBOOK      NVISION2     NVS_RPTBK_INCXXX                        8
nVision-ReportBook             RPTBOOK      NVISION2     NVS_RPTBK_MORYYY1                       8
nVision-ReportBook             RPTBOOK      NVISION      NVS_RPTBOOK_24                          9
nVision-ReportBook             RPTBOOK      NVISION      NVS_RPTBOOK_16                          9

A Test Script

This test script inserts some dummy rows into PSPRCSQUE to check whether a priority is assigned by the trigger. The insert is then rolled back.

INSERT INTO psprcsque (prcsinstance, prcstype, prcsname, oprid, runcntlid)
VALUES (-42, 'nVision-ReportBook', 'RPTBOOK', 'NVISION','NVS_RPTBOOK_17');
INSERT INTO psprcsque (prcsinstance, prcstype, prcsname, oprid, runcntlid)
VALUES (-43, 'nVision-ReportBook', 'RPTBOOK', 'NVISION','NVS_RPTBOOK_STAT1');
select prcsinstance, prcstype, prcsname, oprid, runcntlid, prcsprty from psprcsque where prcsinstance IN(-42,-43);
rollback;

You can see that it was successful because priorities 2 and 7 were assigned.

PRCSINSTANCE PRCSTYPE                       PRCSNAME     OPRID        RUNCNTLID                        PRCSPRTY
------------ ------------------------------ ------------ ------------ ------------------------------ ----------
         -43 nVision-ReportBook             RPTBOOK      NVISION      NVS_RPTBOOK_STAT1                       2
         -42 nVision-ReportBook             RPTBOOK      NVISION      NVS_RPTBOOK_17                          7

Monitoring Script

This query in script process_prioritisation_by_cumulative_runtime_report.sql reports on the average, median, and cumulative median execution time for each nVision process that ran to success during the overnight processing window as calculated by the package GFCPRCSPRIORITY and stored in PS_XX_GFCPRCSPRTY.  It also compares that to the priority and last actual run time for that process.

Example Output

                                                                                                      Cum.                                            
                                                                        Average   Median            Median    Total         Last Run   Actual                   
                                                                  Prcs Duration Duration Duration Duration Duration     Num  Process Duration Duration Duration Priorty
PRCSTYPE             PRCSNAME   OPRID        RUNCNTLID            Prty   (mins)   (mins)   (mins)   (mins)   (mins) Samples Priority   (mins)    Diff    % Diff    Diff
-------------------- ---------- ------------ -------------------- ---- -------- -------- -------- -------- -------- ------- -------- -------- -------- -------- -------
nVision-ReportBook   RPTBOOK    NVISION      NVS_RPTBOOK_4           9    90.65      131      209     1834     1997      23        6      189       58       44       3 
nVision-ReportBook   RPTBOOK    NVISION      NVS_RPTBOOK_16          9   159.17      163      209     1997     1997      23        9      177       14        9       0

nVision-ReportBook   RPTBOOK    NVISION      NVS_RPTBOOK_14          8    89.26      127      215     1703     1997      23        6      167       40       31       2
nVision-ReportBook   RPTBOOK    NVISION      NVS_RPTBOOK_24          8   115.87      117      165     1576     1997      23        9      144       27       23      -1

nVision-ReportBook   RPTBOOK    NVISION2     NVS_RPTBK_MORYYY1       7    93.13       85      165     1459     1997      23        8      158       73       86      -1
nVision-ReportBook   RPTBOOK    NVISION      NVS_RPTBOOK_28          7    88.30       80      172     1374     1997      23        8      108       28       35      -1

nVision-ReportBook   RPTBOOK    NVISION2     NVS_RPTBK_INCXXX        6    83.61       79      149     1294     1997      18        7      118       39       49      -1
nVision-ReportBook   RPTBOOK    NVISION      NVS_RPTBOOK_17          6    70.96       69      105     1143     1997      23        7       81       12       17      -1
nVision-ReportBook   RPTBOOK    NVISION      NVS_RPTBOOK_STAT4       6    68.00       72       81     1215     1997       8        7       81        9       13      -1

nVision-ReportBook   RPTBOOK    NVISION2     NVS_RPTBK_MMMMMM        5    52.45       46      119      914     1997      22        5       91       46      100       0
nVision-ReportBook   RPTBOOK    NVISION2     NVS_RPTBK_TEMPXX        5    50.48       49      104      963     1997      23        5       94       45       92       0
nVision-ReportBook   RPTBOOK    NVISION      NVS_RPTBOOK_3           5    55.52       55       99     1018     1997      23        6       79       24       44      -1
nVision-ReportBook   RPTBOOK    NVISION      NVS_RPTBOOK_1           5    47.70       56      137     1074     1997      23        4       56        0        0       1
…

Monitoring Query

The query in prcsmap.sql is used to produce the data for a map of the processes, showing request time, time spent queuing, and time spent executing.  It is the basis of the second chart above. I normally run this in SQL Developer and export the data as an Excel workbook.  There is an example spreadsheet in the Github repository.

9 levels of Prioritisation

With prioritisation, we can see that the long-running jobs with higher priority ran earlier.  

We can also see that some of the higher-priority jobs that are scheduled later are running earlier than those scheduled earlier, and are thus finishing earlier.

There is no longer any tail of processing.  Instead, load drops quickly at the end of the batch, and the batch as a whole finishes earlier.